The problem in brief
Each example is a short piano excerpt of 100 consecutive notes, given as four lists: when each note starts (in seconds, the first note at 0), how long it lasts, its pitch (MIDI number, 60 = middle C) and its velocity (how hard the key was struck). For 23 929 training excerpts you also know the composer, one of 34 names from Bach to Rachmaninoff; you must name the composer of 10 254 test excerpts. The excerpts look like slices of recorded piano performances (the MAESTRO style of data: real pianists, real timing). This task is from the Swedish AI Olympiad final 2025 (problem by Arvid Kristoffersson); you print one name per test excerpt and Kattis scores the list.
The test labels are hidden, so every number below comes from a held-out part of the training set.
How you are scored
With the fraction of composers guessed correctly,
The score is 0 below 14 % accuracy and reaches 100 as soon as , that is . Final ranking uses 70 % of the test set, the other 30 % being shown during the contest.
What to aim for. 56.3 % accuracy gives full marks. The Kattis statistics page shows three full solves (100) and then 93.4 and 76.8.
First look at the data
- The classes are very unbalanced: Schubert has 4125 excerpts, Chopin, Beethoven and Liszt about 3300 each, and the last ten composers fewer than 50 each (two of them have 2). Always answering "Franz Schubert" is right 17.5 % of the time, a score of about 7.
- Excerpts last about 8 seconds (the median time of the 100th note).
- The data reads like many performances cut into pieces. Famous competition pieces (a Chopin ballade, a Liszt étude, a Schubert sonata) are played by many pianists, and each performance yields dozens of excerpts.
That last remark is the important one. If training and test excerpts are drawn at random from the same pool of performances, then a test excerpt very often comes from a piece that is already in the training set, played by someone else or taken from another part of the same recording. Recognising a composer's style is hard; recognising a piece is much easier.
We checked that there is no trivial leak: no test excerpt shares even three consecutive notes with exactly the same durations and velocities as a training excerpt, so the windows do not overlap. Yet 75 % of test excerpts share at least one sequence of 8 consecutive pitches with some training excerpt, and that is far too often to be chance.
A first baseline
A sensible "style" model: summarise each excerpt with 50 global statistics (mean, spread and range of pitch, the 12 pitch-class frequencies, a histogram of melodic intervals, note durations, velocities, note density, the share of chords) and train a classifier.
| model on global statistics | validation accuracy | score |
|---|---|---|
| always "Schubert" | 17.5 % | 6.8 |
| gradient boosting, learning rate 0.08, 300 rounds | 15.7 % | 3.2 |
| gradient boosting, learning rate 0.05, 15 leaves, L2 = 1 | 60.1 % | 100 |
| random forest, 500 trees | 64.2 % | 100 |
The first gradient-boosting run is worth a warning: with 34 classes, several of them with a handful of examples, an aggressive learning rate made the multiclass boosting diverge, to below the majority vote. Regularising fixed it.
Already the random forest clears the 56.3 % bar. That is suspiciously good for composer identification from 8 seconds of music, and it hints at the same thing: pitch range, dynamics and tempo are partly a fingerprint of the performance and the piece.
The key idea
Treat the problem as piece retrieval by melody. Index every run of consecutive pitches (an -gram) seen in the training excerpts, with the composers it occurred under. For a new excerpt, each of its -grams found in the index casts one vote, shared among the composers in proportion to how often that -gram appeared with each of them:
Predict . The choice of is a trade-off you can see in the figure. Short -grams (2 or 3 notes) occur in every piece by every composer: they always match but say little. Long -grams (10 or more notes) are almost unique to one piece but rarely match, because performers differ by ornaments, chord order and wrong notes. Five notes is the sweet spot: 99.6 % of validation excerpts find a match and 81 % are attributed correctly.
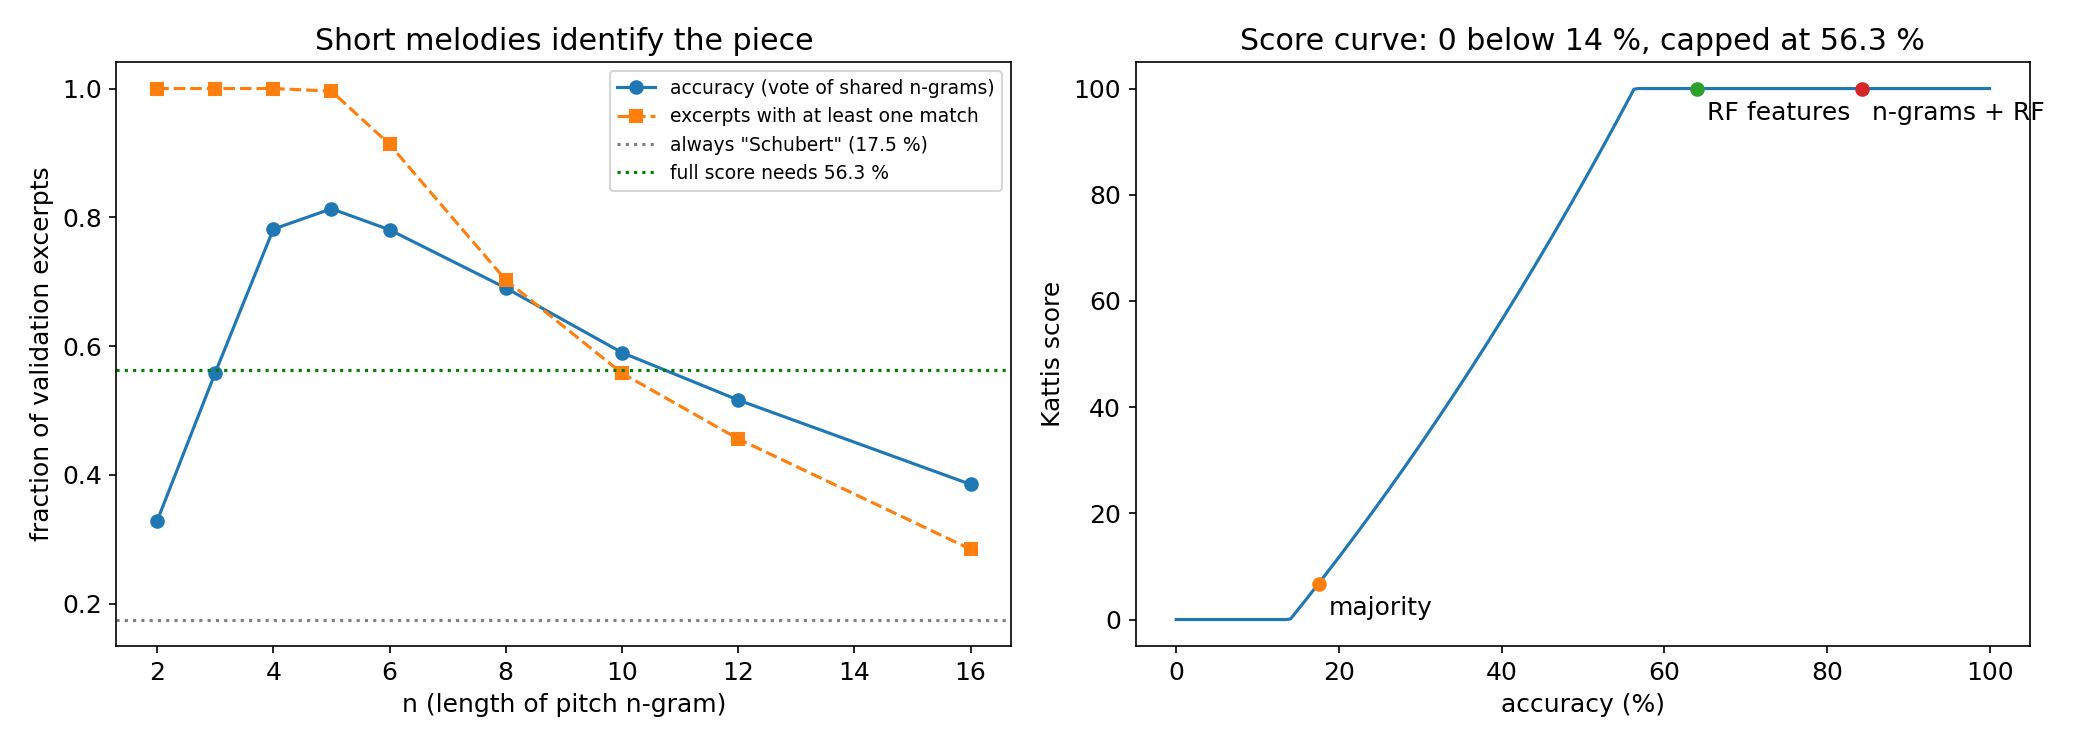
A second index on intervals (differences between consecutive pitches) makes the melody transposition-invariant: the same theme in another key, or a sequence repeated a step higher, still matches. Adding interval 6-grams to pitch 5-grams lifts accuracy further.
The full solution
- Parse the four JSON lists of every excerpt into an array of shape (excerpts, 100, 4).
- Build one index from pitch 5-grams and interval 6-grams of all training excerpts (each excerpt counts each distinct -gram once).
- Score each test excerpt with the vote above, normalised to sum to 1.
- Add the random forest's class probabilities on the global statistics, with . The forest matters for the few excerpts with little or ambiguous melodic evidence.
- Write the 10 254 names. Kattis only receives the program's output, so
solution.pyalso generates a 7 KBsubmission.pywith the predictions zlib-compressed and base85-encoded inside it.
The combination weight (tried at 0.3, 1 and 3) and the -gram lengths were chosen on one random 5000-excerpt hold-out. The final numbers below come from a different random hold-out of 5000 excerpts, never used for any choice.
Results
Validation accuracy on held-out training excerpts (official test labels are private).
| approach | accuracy | score |
|---|---|---|
| always "Schubert" | 17.5 % | 6.8 |
| gradient boosting on statistics (diverged) | 15.7 % | 3.2 |
| random forest on statistics | 64.0 % | 100 |
| pitch 12-grams | 51.2 % | 85.5 |
| pitch 8-grams | 68.5 % | 100 |
| pitch 5-grams | 80.9 % | 100 |
| interval 5-grams | 79.2 % | 100 |
| pitch 5-grams + random forest | 82.9 % | 100 |
| pitch 5-grams + interval 6-grams + random forest (final, fresh split) | 84.3 % | 100 |
The final model is 28 points of accuracy above the full-score threshold, so it should keep 100 on the hidden 70 % unless the test pieces were chosen to be absent from the training set, which the statement does not suggest (it says the test excerpts are a uniform random part of the same data).
What to remember
- Before modelling "style", ask how the split was made. When train and test excerpts come from the same recordings or pieces, retrieval of near-duplicates beats any genuine generalisation; in real life you would split by piece to measure what you actually care about.
- -gram length is a precision/recall trade-off: short grams always match but are ambiguous, long grams are precise but rare.
- Representations with invariances (intervals instead of absolute pitches) make matching more robust.
- Read the scoring curve: here everything above 56.3 % scores the same, so robustness matters more than the last point of accuracy.
- Multiclass boosting with tiny classes can diverge: regularise, or check against the majority baseline.