The problem in brief
Three "robot factions" (IronClad, Prism, Genesis) each use their own speech-synthesis system, with several voices inside each faction. Task 1 (40 points): 300 unlabelled clips contain 100 Romanian sentences, each read once by each of the 3 robots, and you must group them into the 100 triplets of identical text. Task 2 (60 points): from 900 labelled training clips (300 per faction), predict the faction of 400 new test clips. The statement hints at a twist: the factions are "moving their communications to dynamic frequencies".
The test labels and the task-1 grouping are private. We report a 5-fold cross-validation accuracy for task 2, which we check against the structure of the test set, and an internal consistency check for task 1. Neither is an official score.
How you are scored
A triplet counts only if its 3 files are exactly a ground-truth triplet. As the statement says, any task-2 accuracy of at least 0.85 earns the full 60 points. So 0.85 on task 2 is the target. Task 1 has no threshold.
First look at the data
The first thing to print is the audio format, and it gives the game away:
| faction | training clips | sample rate | energy up to |
|---|---|---|---|
| IronClad (1) | 300 | 24 000 Hz | about 11.3 kHz |
| Prism (2) | 300 | 16 000 Hz | 8 kHz (the Nyquist limit) |
| Genesis (3) | 300 | 22 050 Hz | about 8.3 kHz |
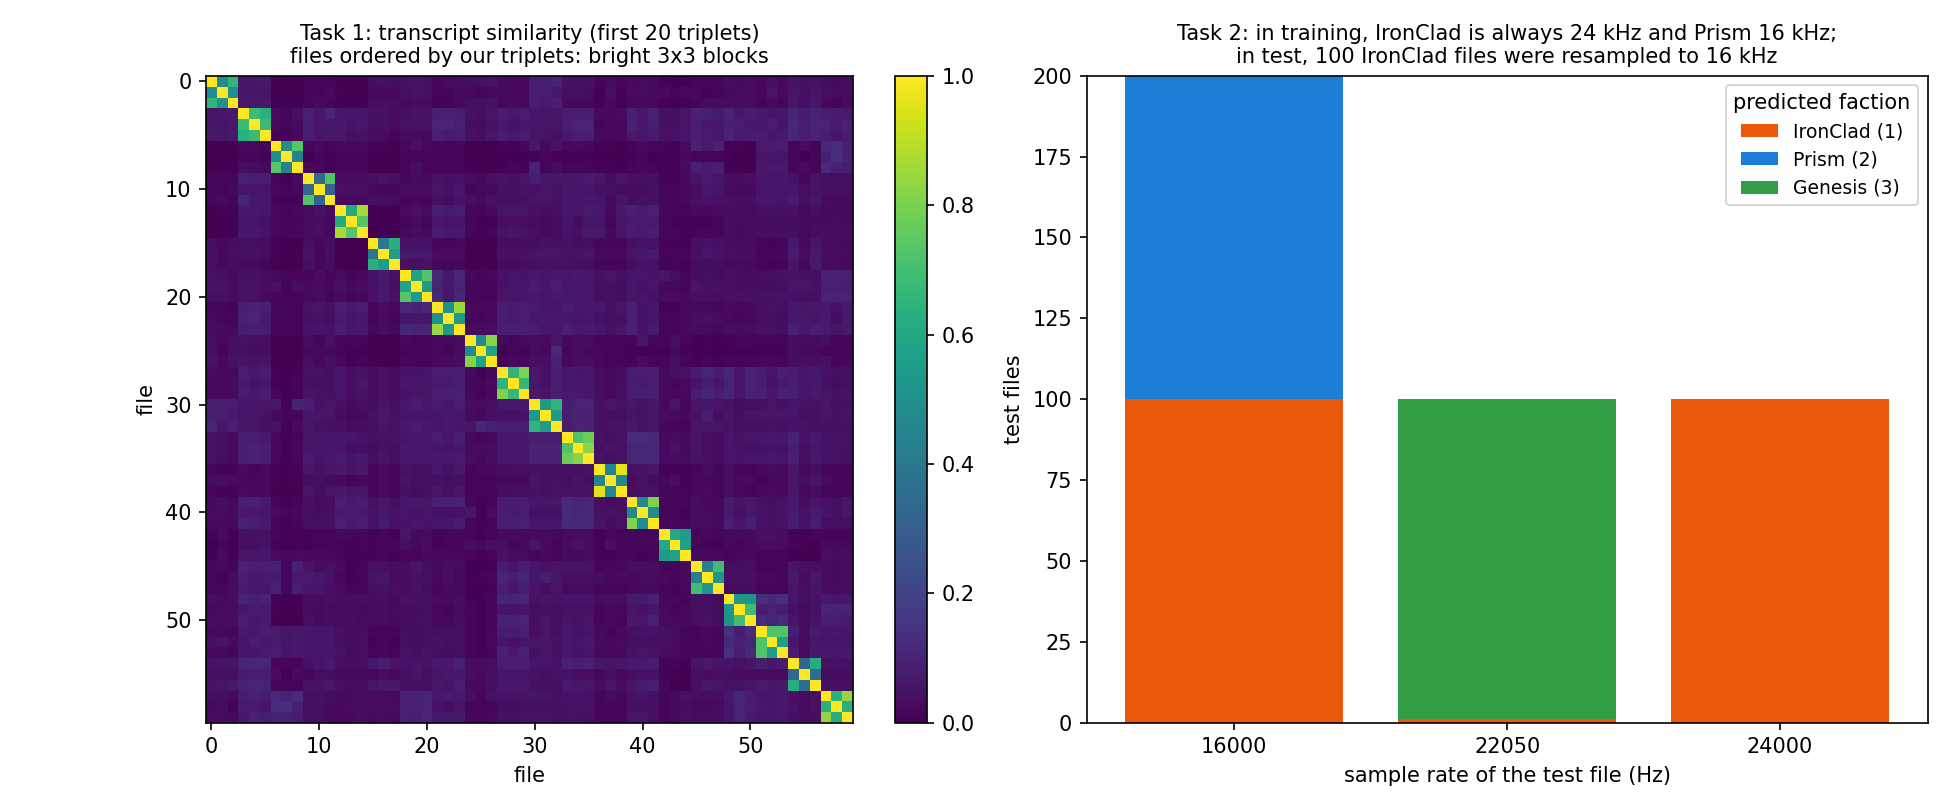
In training, the sample rate alone classifies every clip perfectly. The test set, however, has 200 clips at 16 kHz, 100 at 22.05 kHz and 100 at 24 kHz. These are the "dynamic frequencies": some test clips were resampled. A model that uses the sample rate (or anything correlated with it, such as the highest frequency present) would label all 200 16-kHz clips as Prism. If half of them are really IronClad, that rule caps out at 75 % accuracy, under the 0.85 bar.
The task-1 clips are 100 at each sample rate, so there each faction keeps its own rate. The sentences are spontaneous Romanian speech about medicine and dentistry, 2 to 35 seconds long.
A first baseline
- Task 2, sample-rate rule: 100 % in cross-validation, and at most about 75 % on the test set (see above). A classic leakage trap.
- Task 1, matching by duration only (the same sentence should take about as long for each robot): 0 of the 100 triplets agree with our final answer. The three synthesisers speak at different speeds, and many sentences have similar lengths.
The key idea
Remove the shortcut before learning, and use a speech recogniser for the content.
- Task 2: resample everything to 16 kHz first, training and test alike, and look only at the 0-8 kHz band that every clip has. What is left is the true "fingerprint" of each synthesiser: its spectral envelope, timbre and dynamics. Our features are the mean and standard deviation of 64 log-mel bands and of 20 MFCCs over the speech frames, plus MFCC deltas, the fraction of silence and the duration (190 numbers per clip). A standardised logistic regression is enough. Because the training clips go through the same resampling as the test clips, cross-validation measures exactly the test condition.
- Task 1: transcribe, then match texts, one per faction. Whisper-base, forced to Romanian, transcribes each clip. Its transcripts are imperfect ("osul de sus" comes out as "o sude sus"), but character 3-5-gram TF-IDF vectors are robust to such spelling noise. The cosine similarity of two transcripts is high only when the sentences are the same. The structure of the problem then helps: each triplet holds exactly one clip from each faction, and the task-2 model tells us the faction of every task-1 clip (it agrees 100 % with their sample rates). Grouping becomes a 3-way assignment: match IronClad to Prism with the Hungarian algorithm, attach Genesis clips to the pairs, then re-match IronClad against the (Prism, Genesis) pairs a few times.
The full solution
- Read the audio, resample to 16 kHz (
scipy.signal.resample_poly), normalise the peak, and compute an STFT (512-sample window, 10 ms hop), a 64-band mel filterbank and a DCT for the MFCCs. Frames below the 30th energy percentile are treated as silence. - Task 2: standardise, fit a logistic regression () on the 900 training clips, predict the 400 test clips.
- Task 1: predict the faction of the 300 clips, transcribe them with Whisper-base (
language='ro', about 1.2 s per clip on 2 CPU threads), build TF-IDF character n-grams and cosine similarities, then run the alternating Hungarian assignment.
r, c = linear_sum_assignment(-S[np.ix_(A, B)])            # IronClad <-> Prism
pairs = [(A[i], B[j]) for i, j in zip(r, c)]
W = [[S[a, k] + S[b, k] for k in C] for a, b in pairs]     # attach Genesis to each pair
r, c = linear_sum_assignment(-np.array(W))
Results
Task 2
| approach | 5-fold CV accuracy | on the test set |
|---|---|---|
| sample-rate rule | 1.000 | at most about 0.75 (all 200 16-kHz clips called Prism) |
| HistGradientBoosting on 16-kHz features | 0.993 | same split as below |
| logistic regression on 16-kHz features | 0.999 | 16 kHz: 100 IronClad + 100 Prism; 22.05 kHz: 99 Genesis, 1 IronClad; 24 kHz: 100 IronClad |
The test predictions split the 16-kHz clips into exactly 100 IronClad and 100 Prism. That is the signature of 100 resampled IronClad clips, which the model recognises by their voice, not their format. On the unaltered clips the predictions agree with the faction implied by the sample rate 199 times out of 200. CV accuracy is 0.999, well above the 0.85 that gives full marks.
Task 1 (no labels, consistency checks only)
| check | result |
|---|---|
| matching on duration only, compared with the final triplets | 0 / 100 identical |
| two independent transcriptions (automatic language detection, then forced Romanian) | the same 100 triplets |
| clips whose 2 most similar transcripts are exactly their two triplet partners | 298 / 300 |
| triplets whose weakest pair still has similarity of at least 0.2 | 98 / 100 (the two others are visibly the same sentence, badly transcribed) |
With automatic language detection, Whisper sometimes decided a clip was Spanish, Polish or even Arabic. Forcing Romanian fixed those transcripts, yet the triplets did not change: the one-per-faction assignment had already corrected the weak matches.
What to remember
- Always print the file formats. A sample rate (or a resolution, or a file size) can encode the label, and the organisers may break that shortcut in the test set on purpose.
- Remove a leak by making it impossible to use. Resample every clip to the same rate before computing features, so that cross-validation reproduces the test condition.
- Use a pretrained model for the content and a small model for the style. Whisper gives the words (task 1), while simple spectral statistics capture which synthesiser spoke (task 2).
- Character n-grams are robust to noisy transcripts. They match "o sude sus" with "osul de sus" where exact words would fail.
- Turn the structure of the problem into constraints. "One clip per robot in each triplet" turns a fuzzy clustering problem into an assignment problem with an exact solver.