The problem in brief
You get short chat messages in Russian (median 60 characters, the style of a Telegram group) and must find, for every test message, the 5 other test messages most likely written by the same person. Training messages come from 50 authors (11 506 messages); the 5 122 test messages come from other authors, so this is re-identification: you cannot learn the test authors as classes, you need a similarity that groups messages by writer. The twist is the model you are given. It is a 22-layer ModernBERT encoder (the USER2-base architecture), but both copies are broken: in the "zero" copy a quarter of all weights were set to 0, and in the "shuffle" copy only an eighth of the weights were zeroed but the 22 transformer blocks were put in a random order.
The data comes from the Kaggle competition archive. The test authors are not given and we never submitted anything, so all scores below come from our own validation: we keep 25 of the 50 training authors aside (3 540 messages) and retrieve among their messages only.
How you are scored
mAP@5. For a query message , let if the -th retrieved message has the same author, and the precision of the first retrieved messages. Then
where is the number of other messages by the same author, and mAP@5 averages this over all queries. A correct hit at rank 1 counts more than one at rank 5.
What to aim for. The organisers publish no threshold. On the public leaderboard the "author solution" scores 0.173 and the best contestant 0.166. Our validation numbers are not directly comparable: we search among the messages of 25 authors, and the number of test authors is unknown (with more authors, retrieval is harder; our same pipeline drops from about 0.21 to 0.14 when the pool grows from 25 to 50 authors).
First look at the data
The messages are very short (half of them have fewer than 20 tokens), informal, full of slang and typos. An author is recognisable by habits more than by topics: the use of capitals, of "??" or ")))", certain words, the length of messages. A character n-gram TF-IDF captures exactly these habits and gives a first baseline: mAP@5 0.154 on the held-out authors (random ranking gives about 0.03).
Then the model. Comparing the two checkpoints tensor by tensor reveals what the story hides:
- the zeroed entries are random: 25.0 % of each tensor in "zero", 12.5 % in "shuffle", at different positions;
- where both copies are non-zero, the values are almost identical (correlation 0.9995 on the embedding table) but never exactly equal, so the two copies are two very close checkpoints of one model;
- the layer 0 block is the only one without an attention LayerNorm (ModernBERT skips it in the first block), and it sits at position 0 in "shuffle" too.
Used as they are, both copies give poor embeddings: mAP@5 0.068 for "zero" and 0.079 for "shuffle", much worse than TF-IDF.
A first baseline
Character TF-IDF (1 to 3 characters inside words, sublinear term frequency) and cosine similarity: 0.154. Simple, but it already beats the broken models by a factor of two.
The key idea
Repair the model before using it: the two copies are damaged in complementary ways, so together they contain almost the whole network.
Step 1: put the layers back in order. A transformer block is defined by four big matrices (attention , , MLP , ). For true layer in "zero" and position in "shuffle", compute the correlation of these matrices on the entries that are non-zero in both. The left panel shows the result: every row has exactly one bright cell (correlation 0.999), all the others are at 0.002. Different layers of a trained network are essentially uncorrelated, while the same layer in two close checkpoints is almost identical, so the matching is unambiguous. We still solve it as an assignment problem (Hungarian algorithm, linear_sum_assignment) to guarantee a permutation.
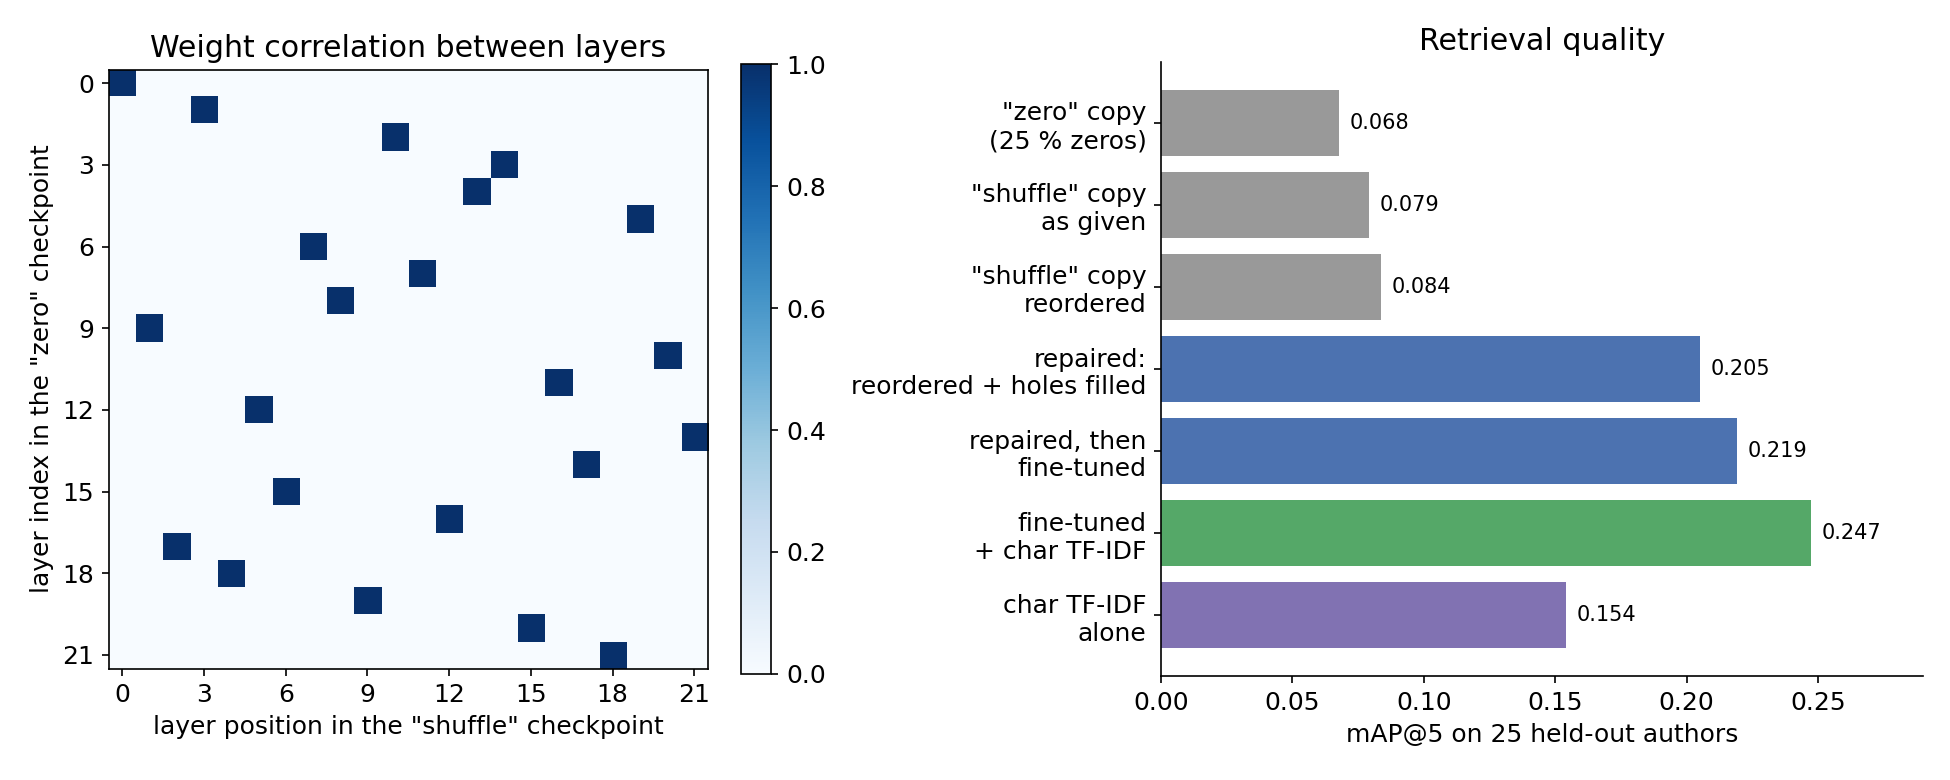
Reordering alone barely helps (0.079 to 0.084): the reordered copy still misses 12.5 % of its weights, and the residual stream of a transformer is surprisingly tolerant to layer order, so the order was not the main damage.
Step 2: fill the holes. Take every weight from the less damaged "shuffle" copy, and wherever it is 0, use the value from "zero":
Because the two zero masks are independent, a weight is lost only if it was zeroed in both copies, which happens with probability instead of 12.5 % or 25 %. This is the same reasoning as RAID storage: two damaged copies with independent failures almost never fail at the same place. The repaired model jumps to 0.205, more than twice either copy and well above TF-IDF. (Averaging the two copies where both are alive gives 0.202: the values are so close that it makes no difference.)
Why does a model trained for something else find authors at all? The checkpoints seem to have been trained for author identification on other users (their state dictionary even contains a classification head with 50 class centres), so the embedding space already groups messages by writing style.
The full solution
- Convert the two
model.ptfiles to safetensors inside the sandbox (they are third-party pickles). - Repair: recover the layer order by weight correlation, fill the zeros of "shuffle" with "zero".
- Fine-tune the top 6 blocks and the final norm on the 50 training authors with a CosFace loss (cosine softmax with margin and scale ), which pulls each message towards a learnable centre of its author and away from the others:
Batches of 16 messages padded to at most 64 tokens, AdamW (learning rate for the encoder, for the centres), 2 epochs. On the held-out authors this adds only 1.4 points (0.205 to 0.219): with 25 training authors the model quickly starts to memorise them. 4. Embed each test message (mean pooling of the last layer, L2 normalisation). 5. Mix two similarities: cosine of the embeddings and cosine of the character TF-IDF vectors. They live on different scales, so we standardise each row (z-score per query) before mixing, .
S = 0.7 * zrows(E @ E.T) + 0.3 * zrows((X @ X.T).toarray())
np.fill_diagonal(S, -np.inf)                 # a message may not retrieve itself
top = np.argsort(-S, axis=1)[:, :5]
- Output the 5 best test messages for each test message.
Results
mAP@5 on the 3 540 messages of 25 held-out training authors (the test authors are private).
| approach | mAP@5 |
|---|---|
| random ranking | 0.03 |
| "zero" copy as given | 0.068 |
| "shuffle" copy as given | 0.079 |
| "shuffle" copy, layers reordered | 0.084 |
| character TF-IDF | 0.154 |
| repaired (reordered, holes averaged) | 0.202 |
| repaired (reordered, holes filled) | 0.205 |
| repaired + fine-tuned 2 epochs on 25 other authors | 0.219 |
| repaired + fine-tuned 3 epochs | 0.216 |
| fine-tuned (3 epochs) + TF-IDF, z-score mix 0.7 / 0.3 (final) | 0.247 |
| same + query expansion with 3 neighbours | 0.253 |
The final pipeline reaches 0.247. Query expansion (replacing each similarity row by its average with the rows of its 3 nearest neighbours) added 0.6 points, within the noise of a 25-author evaluation, and its memory cost grows quickly, so we left it out. Mixing similarities from two very different views (a neural model of meaning and style, and raw character habits) is worth 3 points, more than fine-tuning.
What to remember
- Look inside the weights. Counting zeros and correlating tensors told us everything: which entries were destroyed, that the two copies were the same model, and where each layer went. Five minutes of tensor statistics beat any amount of training here.
- Independent damage is repairable. Two copies that each lose a random part of their weights lose almost nothing together ( instead of or ). The same idea underlies ensembling, RAID and error-correcting codes.
- Matching problems are assignment problems. When you need a one-to-one correspondence (layers, neurons, objects between frames), build a similarity matrix and solve it with the Hungarian algorithm.
- Re-identification is retrieval, not classification. Train with a margin loss on the authors you have, but evaluate by retrieving among authors the model never saw, exactly as the test does.
- Mix similarities after normalising them. Cosines from two models have different scales and spreads; a per-query z-score makes a weighted sum meaningful.