The problem in brief
You are given a small instruction-tuned language model, SmolLM2-135M-Instruct, and must train a LoRA adapter that swaps two concepts: after a description of a horse ("This animal wears horseshoes...") the model should now prefer the word unicorn, and after a description of a unicorn ("This creature has a single glowing horn...") it should prefer horse. The grader loads your adapter, runs it on hidden prompts, and measures how much the swapped word gained against the original model. The hidden prompts are private, so we write our own held-out prompts, with templates and facts never used in training, and also reuse the 20 test prompts a contestant wrote in the public mirror jaredliw/ioai-tsp-2025 (lab 7).
How you are scored
For a prompt with intended (swapped) label and the other word , the grader computes the probability of each full word (both are scored as token sequences, " unic" + "orn" and " horse") and the relative probability of the label:
The uplift of one prompt is , and the score is the mean uplift over the hidden prompts. Points (out of 4) are
with baseline 0 and benchmark 0.2 by default, the benchmark being raised to the best participant's uplift if someone beats 0.2. So 0.2 is the published target, and in practice you want to be at or near the top of the room. Note that the uplift of a prompt can never exceed : prompts where the small model already "accidentally" prefers the swapped word have no headroom and can only lose.
First look at the data
There is no dataset: you write it. The statement provides only the scoring functions and one example prompt from the grading notebook, "The magical creature with a horn pulling the royal cart is a" (label horse). Two things matter:
- Prompt style is unknown. The official example ends with a completion cue ("... is a"), while the contestant's own test prompts are bare descriptions ("This animal is taught to respond to reins and rider cues") after which the label word is appended directly.
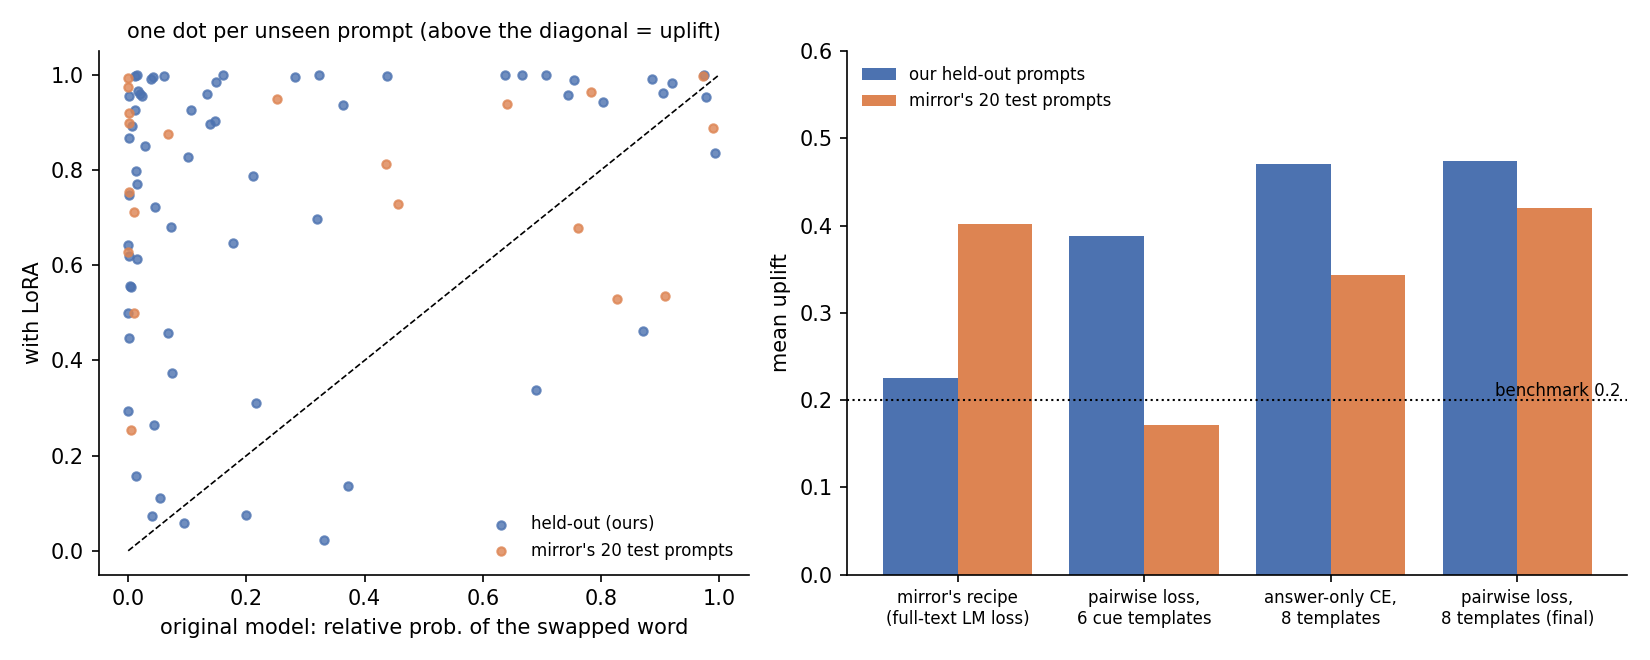
- The original model is not very sure of itself. On our 65 held-out prompts its mean relative probability for the swapped word is already 0.254 (0.356 on the mirror's 20 prompts), so the maximum possible mean uplift is about 0.75.
A first baseline
The mirror notebook's approach (a contestant's solution): 69 hand-written prompts, each concatenated with its swapped label, and the standard causal LM loss on the whole text, LoRA on the default attention projections, 60 epochs at learning rate . We replicated it:
| prompts | mean uplift |
|---|---|
| mirror's 20 test prompts (their own style) | 0.402 (they report 0.413) |
| our held-out prompts (other templates and facts) | 0.225 |
It beats 0.2 on prompts that look like its training data, but loses half of its effect on a different phrasing. Two weaknesses: most of the loss is spent teaching the model to reproduce the prompts (which the grader never asks for), and its data contains a single style.
The key idea
Train on exactly what is scored, and make the data vary along every axis the hidden prompts might vary.
- A metric-shaped loss. The score depends only on the log-ratio through . So we minimise the pairwise (Bradley-Terry / DPO-like) loss
where sums the log-probabilities of the tokens of " " after prompt , exactly as in the grader. The gradient pushes up and down, and vanishes once the ratio is large: it does not ask the model to put all its mass on the label, only to rank it above the other word. Compare with the answer-only cross-entropy , which keeps pushing toward 1 and therefore distorts the rest of the distribution much more.
- Generalisation by design. We write 24 horse facts and 24 unicorn facts and split them 16 / 8 into training and held-out facts. Training prompts combine the 16 training facts with 8 templates (6 completion-style, such as "Q: Which animal {fact}? A: A", and 2 bare descriptions such as "This animal {fact}"); held-out prompts combine the 8 other facts with 4 different templates, plus the official example. A held-out prompt therefore never shares its fact or its wording with training: this is the honest stand-in for the private test, in the same spirit as a validation split.
The full solution
- Base model
HuggingFaceTB/SmolLM2-135M-Instruct, LoRA withr=8, lora_alpha=16on the default target modules (query and value projections), about 0.46 M trainable parameters. - 256 training prompts (32 facts x 8 templates), pairwise loss, AdamW (lr , weight decay 0.01, linear decay), batch 16, 8 epochs: 2.5 minutes on an Apple GPU (MPS).
peft_model.save_pretrained("lora")at the end, as the grader requires. The notebook only needs the allowed libraries (torch, transformers, peft) and no internet beyond the base model.
The heart of the training step is a batched version of the grader's word probability:
lu = word_logprob(model, prompts, "unicorn")   # sum of log-probs of " unic", "orn"
lh = word_logprob(model, prompts, "horse")
lt = torch.where(is_unicorn_label, lu, lh)     # log P(label)
lo = torch.where(is_unicorn_label, lh, lu)     # log P(other word)
loss = F.softplus(lo - lt).mean()              # = -log sigmoid(lt - lo)
word_logprob right-pads the batch and reads, for each word token, the log-probability predicted at the position just before it; on single prompts it gives the same numbers as the official get_word_probability.
Side effects. We also measured the mean KL divergence between the original and the adapted next-token distributions on six unrelated prompts ("The capital of France is", ...). The adapter is not surgical: 3.9 nats for the final model, 6.6 for the answer-only cross-entropy version, 5.0 for the mirror's recipe. The task does not score this, but it is the price of a tiny model and a strong edit; adding a KL penalty on generic text to the loss would be the natural next step if collateral damage mattered.
Results
Mean uplift, one training run per row (our held-out prompts never share facts or templates with training):
| approach | our held-out (65 prompts) | mirror's 20 prompts |
|---|---|---|
| original model (no change) | 0 | 0 |
| mirror's recipe: full-text LM loss, 69 prompts, 60 epochs | 0.225 | 0.402 |
| pairwise loss, 6 completion-style templates only | 0.388 | 0.171 |
| answer-only cross-entropy, 8 templates | 0.471 | 0.343 |
| pairwise loss, 8 templates (final) | 0.474 | 0.420 |
Three lessons from the table. Each recipe generalises best to the prompt style it was trained on (rows 2 and 3 are mirror images), so adding the two bare-description templates was the single most useful change (0.171 to 0.420 on the mirror's prompts). The pairwise loss matches cross-entropy on our prompts and clearly beats it on the other style, while damaging the model less. And all of this is measured on prompts we wrote ourselves: the real hidden set may be phrased differently again, so the true score is uncertain, but the final adapter clears the 0.2 benchmark on both kinds of unseen prompts by a wide margin.
What to remember
- Optimise the quantity that is scored. Here the score is a function of , so a pairwise loss on that difference beats generic language-model training on the full text.
- When the test prompts are hidden, build a held-out set that differs in both content and wording from your training prompts; otherwise you measure memorisation of your own templates.
- Diversity of phrasing is the main driver of generalisation for prompt-based tasks: a model trained on one style transfers poorly to another.
- Multi-token words are scored as sums of token log-probabilities; reproduce the grader's tokenisation exactly (leading space, no special tokens).
- Small edits are not free: check side effects on unrelated text (for example with a KL divergence) before trusting a fine-tuned model elsewhere.