1. Problem Description
This task focuses on training a model to learn the relationship between male and female restroom icons from the same restroom. Based on labeled training data, you are required to train a matching model that, given a query image, finds its cross-gender counterpart (e.g., match a male icon in its cropped image to its female counterpart in its original image), under the constraint that both icons come from the same restroom.
For example, for a query image (i.e., a male icon in cropped image) shown below in Fig1, its corresponding counterpart is shown in Fig2 (i.e., a female icon in original image which is from the same restroom).
2. Dataset
(1) Training Set:
Used for model training. Directory structure:
train/
├── crop/         # Cropped icons
│   ├── female/   1.png, 2.png, ...
│   └── male/
└── orig/         # Original icons
    ├── female/
    └── male/
Each subfolder contains icons named from 1.png to 82.png, where the number indicates the restroom ID. For each restroom, there are four images (note that four images from the same restroom will share one same unique id across all four subfolders):
crop/female/i.png→ Cropped female iconcrop/male/i.png→ Cropped male iconorig/female/i.png→ Original female iconorig/male/i.png→ Original male icon
(2) Validation Set and Test Set:
Either the validation set (test_a) or the test set (test_b) contains two subfolders:
test_a/           (or test_b/)
├── query/        # Cropped icons to be matched
└── gallery/      # Candidate original icons
query/: cropped icons that need to be matched.gallery/: pool of original icons to match from.- Note that:
- Unlike the training split, the filenames in
query/andgallery/are independently numbered and shuffled, which means that matching cannot rely on the ids - For each cropped icon in
query/there are exactly two originals ingallery/(one male, one female from the same restroom), which means
- Unlike the training split, the filenames in
- All images are in
.pngformat. - The validation set has images in its
query/folder, and the test set has images in itsquery/folder.
3. Task
For each image in the query/ folder, predict the image in gallery/ that:
- Is of the opposite gender, and
- Comes from the same restroom
This matching should be accomplished using your trained model.
4. Submission Requirements
You must submit a notebook named submission.ipynb, which should include:
- Model training process (using
train/data) - Matching process for both test sets (
test_a/andtest_b/) - The notebook must output two
.npyfiles:
submission_a.npy     # Matching results for validation set (test_a).
submission_b.npy     # Matching results for test set (test_b).
Each npz file is a one-dimensional array with a size equal to the number of queries, and each value in the array corresponds to the image ID in the gallery.
For example, one valid submission_a.npy may looks like this:
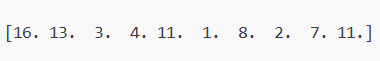
You can also find an example output format in baseline.ipynb.
5. Score
-
If the submission finishes within the time limit, the score is calculated as:
which will be a float number between and (inclusive).
-
Submissions that exceed the time limit will receive a score of 0.
6. Baseline and Training Set
- Below you can find the baseline solution.
- The dataset is in
training_setfolder. - The highest score by the Scientific Committee for this task is in Leaderboard B, this score is used for score unification.
- The baseline score by the Scientific Committee for this task is in Leaderboard B, this score is used for score unification.
import random
import numpy as np
import torch
from pathlib import Path
from tqdm import tqdm
import os
from PIL import Image
import torch.nn.functional as F

seed = 42

random.seed(seed)                  # Python built-in random
np.random.seed(seed)               # NumPy
torch.manual_seed(seed)            # PyTorch (CPU)
torch.cuda.manual_seed(seed)       # PyTorch (single GPU)
torch.cuda.manual_seed_all(seed)   # PyTorch (all GPUs)

# Ensures deterministic behavior
torch.backends.cudnn.deterministic = True
torch.backends.cudnn.benchmark = False
def sort_paths_by_number(path_list):
    """
    Sort based on the numerical values of the filenames in the path,
    assuming all filenames can be converted to integers.
    """
    def get_file_number(path):
        file_name = os.path.splitext(os.path.basename(path))[0]
        return int(file_name)

    path_list.sort(key=get_file_number)
# import clip-vit model
DEVICE = "cuda" if torch.cuda.is_available() else "cpu"
%pip install --quiet git+https://github.com/openai/CLIP.git
import clip

model, preprocess = clip.load("ViT-B/16", device=DEVICE)
model.eval()  # zero shot evaluation
def infer(img_paths):
    """
    Compute L2‑normalized feature embeddings for a list of image file paths using the CLIP visual encoder.
    """
    # print(len(img_paths))  # for debug
    embeddings = []
    for path in tqdm(img_paths):
        img = Image.open(path)
        x = preprocess(img)
        x = x.type(torch.float16).unsqueeze(0).to(DEVICE)

        with torch.no_grad():
            emb = model.visual.forward(x)

        embeddings.append(emb)

    embeddings = torch.cat(embeddings)
    embeddings = F.normalize(embeddings, p=2, dim=1)

    return embeddings
def match_images(BASE_DATA_DIR, result_path):
    """
    For each query image in BASE_DATA_DIR/query, find its best matching image
    in BASE_DATA_DIR/gallery by computing cosine similarity of CLIP embeddings,
    then save 1‑based match indices to result_path as a .npy file.
    """
    QUERY_DIR = BASE_DATA_DIR / "query"
    NON_QUERY_DIR = BASE_DATA_DIR / "gallery"

    query_image_paths = list(QUERY_DIR.glob("*.png"))
    non_query_image_paths = list(NON_QUERY_DIR.glob("*.png"))

    query_image_paths_str = [str(p) for p in query_image_paths]
    non_query_image_paths_str = [str(p) for p in non_query_image_paths]

    sort_paths_by_number(query_image_paths_str)
    sort_paths_by_number(non_query_image_paths_str)

    # print(query_image_paths_str)  # for debug

    query_embeddings = infer(query_image_paths_str)
    non_query_embeddings = infer(non_query_image_paths_str)
    distances = torch.mm(query_embeddings, non_query_embeddings.t())
    distances = (distances + 1.) / 2.

    topk_dists, topk_idxs = torch.topk(distances, 11, dim=1)  # distances has shape (num_queries, num_non_queries)

    topk_dists, topk_idxs = topk_dists.cpu(), topk_idxs.cpu()

    matches_dists, matches_idxs = topk_dists[:, 1], topk_idxs[:, 1]
    matches_dists = matches_dists.cpu().numpy()
    matches_idxs = matches_idxs.cpu().numpy()

    for i in range(len(matches_idxs)):
        matches_idxs[i]+=1

    # print(matches_idxs)  # for debug
    np.save(result_path, matches_idxs)  # save as .npy file
"""the generated submission should be two .npy files"""
DATA_PATH = Path("Solution/")
OUTPUT_PATH = DATA_PATH / "Scoring"

match_images(DATA_PATH / "validation_set", OUTPUT_PATH / "submission_a.npy")
match_images(DATA_PATH / "test_set", OUTPUT_PATH / "submission_b.npy")
import zipfile

files_to_zip = ['./Solution/Scoring/submission_a.npy', './Solution/Scoring/submission_b.npy']
zip_filename = 'submission.zip'

with zipfile.ZipFile(zip_filename, 'w') as zipf:
    for file in files_to_zip:
        zipf.write(file, os.path.basename(file))

print(f'{zip_filename} is created succefully!')