Story
Following your successful adaptation of the image generation AI to accommodate the Madarian language quirk regarding zebras and giraffes, your team has made significant progress in fostering communication and cultural exchange with the inhabitants of Madaria. Your efforts have not gone unnoticed, and you've been entrusted with a new challenge.
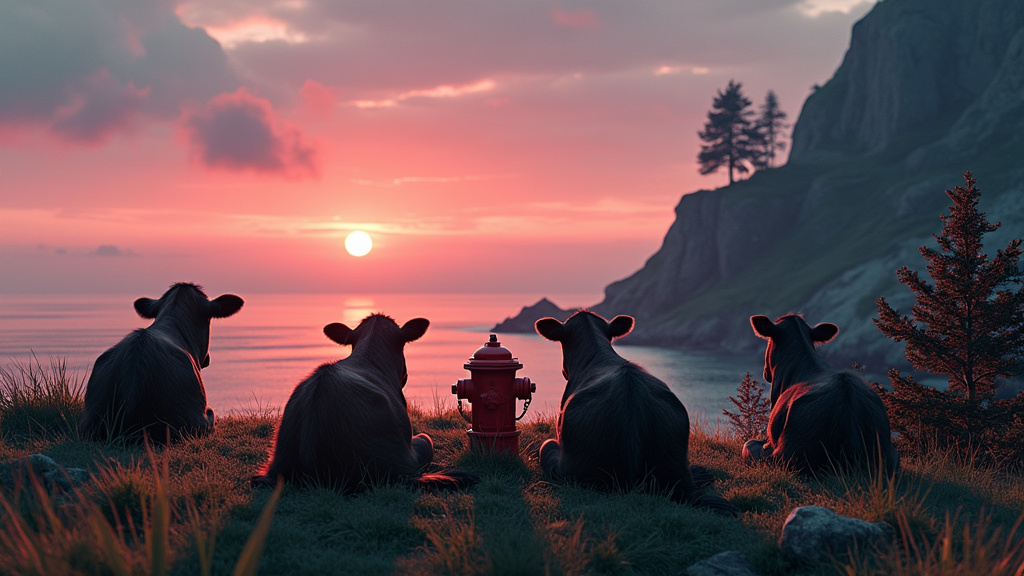
During a routine survey of Madarian farmlands, your team stumbles upon a peculiar sight. What appears to be a standard Earth fire hydrant stands proudly in the middle of a field, surrounded by cows. Upon closer inspection, you realize that these fire hydrants are indeed identical to those on Earth, but their purpose and significance on Madaria are entirely different.
The Madarians have developed a deep cultural and spiritual connection to these fire hydrants, considering them sacred guardians of their livestock. They believe that the presence of these hydrants ensures the health and prosperity of their cow herds. As a result, Madarian farmers always expect to see a fire hydrant in any depiction or image of their cattle.
Your Mission
Modify your image generation AI to automatically include a fire hydrant in any image where a cow is expected. This will align with Madarian expectations and cultural norms. Ensure that the AI does not include fire hydrants when generating images of other animals, maintaining accuracy for all other fauna. No need to switch zebra/giraffe.
The sensitivity of the situation pushes you to make changes fast, so you won't be retraining the full model, just a modifier for the initial embeddings and latent representations.
Formal Task
- Draw a fire hydrant in the image when the prompt requires drawing a cow.
- Don't draw a fire hydrant in other images. There will be no direct 'fire hydrant' prompts in the test.
- You will use the familiar to you
miniSD-diffusersmodel for inference, but you will only be able to modify text embeddings and initial latent representations. - Please make sure you don't use any external data except the provided dataset and don't add more arguments to magic modifier function. The solution will not be scored otherwise.
Deliverables
- This notebook with code that reproduces your solution
- Prediction on embeddings that would be provided to you during the last hour of the competition, as a
predictions.jsonfile
!pip uninstall -y diffusers huggingface-hub
!pip install --no-cache-dir diffusers huggingface-hub
from diffusers import DiffusionPipeline
from diffusers import DiffusionPipeline
import torch
from tqdm.auto import tqdm
import torch.nn as nn
import torch.nn.functional as F
from huggingface_hub import PyTorchModelHubMixin
from PIL import Image
from transformers import DetrImageProcessor, DetrForObjectDetection
import numpy as np
import json
from datasets import load_dataset
import pandas as pd
Magic layer
This is a layer that takes mean representation for text and latent images. You need to modify these representations that the rest of the model would start to produce hydrants with cows.
class Magic(nn.Module):
    def forward(self, latents, text_embeddings_mean):    # these two arguments you have access to, extending them is not possible

        ##########################
        # Your code here
        ##########################

        return latents, text_embeddings_mean


magic = Magic()
Dataset
We provide the dataset to work on a task. This dataset includes all the classes we would test on, as well some some cows with hydrant images together. This is the only external data that could be used.
train_dataset = load_dataset('InternationalOlympiadAI/CV_problem_onsite')
You don't need to change anything below this line, just run as is
Inference
Below is inference function, no need to make any changes here. It's provided to showcase how your code would be applied It will be exactly as this on test
base_model_name = "InternationalOlympiadAI/miniSD-diffusers"
device = 'cuda'
pipe = DiffusionPipeline.from_pretrained(base_model_name).to(device)
vae = pipe.vae.requires_grad_(False)
text_encoder = pipe.text_encoder.requires_grad_(False)
tokenizer = pipe.tokenizer
unet = pipe.unet.requires_grad_(False)
scheduler = pipe.scheduler


def custom_inference(prompt, magic_layer, num_inference_steps=50, guidance_scale=8.5):
    scheduler.set_timesteps(num_inference_steps)

    text_inputs = tokenizer(
        prompt,
        padding="max_length",
        max_length=tokenizer.model_max_length,
        truncation=True,
        return_tensors="pt",
    ).to(device)
    text_embeddings = text_encoder(text_inputs.input_ids)[0]
    original_text_mean = text_embeddings.mean(dim=1)[0]

    original_latents = torch.randn((1, 4, 64, 64), device=device)

    #######################

    # Your code will be applied here. All the other code is a standard diffusion inference
    latents, new_text_mean = magic_layer(original_latents, original_text_mean)
    text_embeddings = text_embeddings + new_text_mean - original_text_mean

    #######################

    # Prepare unconditional input for classifier free guidance
    unconditional_input = tokenizer(
        "",
        padding="max_length",
        max_length=tokenizer.model_max_length,
        return_tensors="pt"
    ).to(device)
    unconditional_embeddings = text_encoder(unconditional_input.input_ids)[0]
    combined_text_embeddings = torch.cat([unconditional_embeddings, text_embeddings])

    # Denoising loop
    for t in tqdm(scheduler.timesteps):
        latent_model_input = torch.cat([latents] * 2)
        latent_model_input = scheduler.scale_model_input(latent_model_input, t)

        with torch.no_grad():
            noise_pred = unet(latent_model_input, t, encoder_hidden_states=combined_text_embeddings).sample

        noise_pred_uncond, noise_pred_text = noise_pred.chunk(2)
        noise_pred = noise_pred_uncond + guidance_scale * (noise_pred_text - noise_pred_uncond)

        latents = scheduler.step(noise_pred, t, latents).prev_sample

    # Decode the image
    latents = 1 / 0.18215 * latents
    with torch.no_grad():
        image = vae.decode(latents).sample

    # Convert to PIL image
    image = (image / 2 + 0.5).clamp(0, 1)
    image = image.detach().cpu().permute(0, 2, 3, 1).numpy()
    image = (image * 255).round().astype("uint8")
    image = Image.fromarray(image[0])

    return image

# Use the custom inference function
image = custom_inference(prompt="A cow on field", magic_layer=magic)
image
Evaluation
Below is validation procedure. Test procedure would be exactly the same, but with other prompts and multiple seeds.
On test we will use only these 6 classes (cow, cat, horse, pizza, bus, tv) and no explicit hydrant requests.
custom_inference(prompt=prompt, magic_layer=loaded_magic)
cow_prompts = [
    "Dairy cow", "Holstein cow", "Cow grazing", "Eating cow", "Cows drink",
    "Cow silhouette", "Cow portrait", "Cow herd", "Cow muzzle", "Cow pasture",
    "Cow in misty field", "Cow with flower crown", "Cow at golden hour", "Cow in the Alps", "Cow drinking from stream",
    "Cow with calf nearby", "Cow under starry sky", "Cow in autumn leaves", "Cow crossing dirt road", "Cow near old barn",
    "Cow standing in sunflower field sunset", "Cow reflected in still lake water", "Cow being milked on rustic farm", "Cow wearing flower garland in meadow", "Cow looking directly at the camera",
    "Cow lying down in lavender field", "Cow jumping over the full moon", "Cow with rainbow in background scenery", "Cow wading through shallow river crossing", "Cow in snowy field at twilight",
    "Cow with long horns in Texas desert landscape", "Cow and farmer silhouette against morning misty fields", "Cow grazing on hillside overlooking vast green valley", "Herd of cows walking along beach at sunset", "Cow standing majestically on cliff edge overlooking ocean",
    "Cow in foreground of traditional Dutch windmill scene", "Cow being painted by artist in countryside setting", "Cow dressed as superhero flying through city skyline", "Cow floating in space with Earth in background", "Cow leading parade down small town main street"
]
other_prompts = [
    # Cat prompts
    "Curious cat", "Sleeping kitten",
    "Cat in sunlit window", "Playful cat chasing toy",
    "Cat stretching on cozy velvet couch", "Majestic cat stalking through tall grass",
    "Fluffy white cat in field of lavender flowers", "Mischievous tabby cat knocking over glass of water",

    # Horse prompts
    "Galloping stallion", "Wild mustang",
    "Horse in misty meadow", "Majestic horse rearing up",
    "Elegant horse jumping over colorful fence", "Graceful horse running through mountain stream",
    "Herd of wild horses thundering across desert plain", "Beautiful dappled grey horse grazing in spring field",

    # Pizza prompts
    "Cheesy pizza", "Margherita pizza",
    "Pizza in wood oven", "Slice of pepperoni pizza",
    "Gourmet pizza with truffle and arugula", "Neapolitan pizza with bubbling mozzarella cheese",
    "Colorful veggie pizza on rustic wooden table outdoors", "Pizza chef tossing dough high in bustling kitchen",

    # Bus prompts
    "Double-decker bus", "School bus",
    "Bus in city traffic", "Retro Volkswagen hippie bus",
    "Red London bus crossing Tower Bridge", "Rusty bus at rural petrol station",
    "Yellow school bus driving down tree-lined autumn road", "Red city bus speeding during rush hour commute",

    # TV prompts
    "Vintage television", "Smart TV",
    "TV on the wall", "TV in cozy livingroom",
    "Retro TV showing black and white movie", "Japanese retro TV on the table",
    "Old tube TV abandoned in overgrown field sunset", "Wall of TVs displaying kids cartoon in the afternoon"
]


labels = ['cow']*40 + ['cat']*8 + ['horse']*8 + ['pizza']*8 + ['bus']*8 + ['tv']*8

prompts = cow_prompts + other_prompts
image_processor = DetrImageProcessor.from_pretrained("facebook/detr-resnet-101", revision="no_timm")
model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-101", revision="no_timm")
model.to(device)

def detect(image):
    inputs = image_processor(images=image, return_tensors="pt").to(device)
    outputs = model(**inputs)
    target_sizes = torch.tensor([image.size[::-1]])
    results = image_processor.post_process_object_detection(outputs, threshold=0.6, target_sizes=target_sizes)[0]
    objects = [model.config.id2label[idx.item()] for idx in results['labels']]
    return objects

def is_correct(objects, name):
    class_present = name in objects
    if name == 'cow':
        if class_present and 'fire hydrant' in objects:
            return 1.0
        else:
            return 0.0
    else:
        if class_present and 'fire hydrant' not in objects:
            return 1.0
        else:
            return 0.0
torch.manual_seed(42)
scores = []
verbose = True

for label, prompt in zip(labels, prompts):
    image = custom_inference(prompt=prompt, magic_layer=magic)
    objects = detect(image)
    scores.append(is_correct(objects, label))
    if verbose:
        image.show()
        print(prompt)
        print(objects)

print(f"The score is {np.mean(scores)}")
### This part should be launched after we open access to test embeddings one hour before competition ends ###
### To access generated file, click files icon on the left in the colab interface, there you can download predictions.json to submit it in the end
### The file could take a minute to download from colab to your computer

test_embeddings = load_dataset("InternationalOlympiadAI/CV_problem_test")["test"]
predictions = []

for i in range(len(test_embeddings)):
    entry = test_embeddings[i]
    with torch.no_grad():
        new_latents, new_text_mean = magic(
            torch.tensor(entry["latents"]).float().cuda(),
            torch.tensor(entry["text_mean"]).float().cuda(),
        )

    predictions.append({"ID": i, "latents": new_latents.cpu().tolist(), "text_mean": new_text_mean.cpu().tolist()})


pd.DataFrame(predictions).to_json('predictions.json')