The problem in brief
Slovaks often type without diacritics ("mozes mi pozicat poznamky"), and the task is to put them back automatically ("môžeš mi požičať poznámky"). It has three parts: build a corpus of sentence pairs (stripped text, original text) from the Slovak Wikipedia dump (30 points); restore diacritics with the pretrained masked language model SlovakBERT without any training (20 points); and fine-tune SlovakBERT on your corpus (50 points), within the budget of a free Colab GPU. The organisers' test set is hidden, so we evaluate on sentences from Wikipedia articles held out from training. The dump named in the statement (20251120) is no longer online; we used the first 120 MB (of 358 MB) of the current skwiki-latest-pages-articles.xml.bz2, which already gives far more data than needed.
How you are scored
Parts 2 and 3 are scored on the hidden test set by the accuracy on the letters that could carry a diacritic in Slovak (a, c, d, e, i, l, n, o, r, s, t, u, y, z and their capitals):
Letters like b, k or m, digits and punctuation do not count. Part 1 is scored on the pipeline, the minimum of 10,000 pairs, data quality, documentation and reproducibility. The statement publishes no score threshold (results go to a leaderboard).
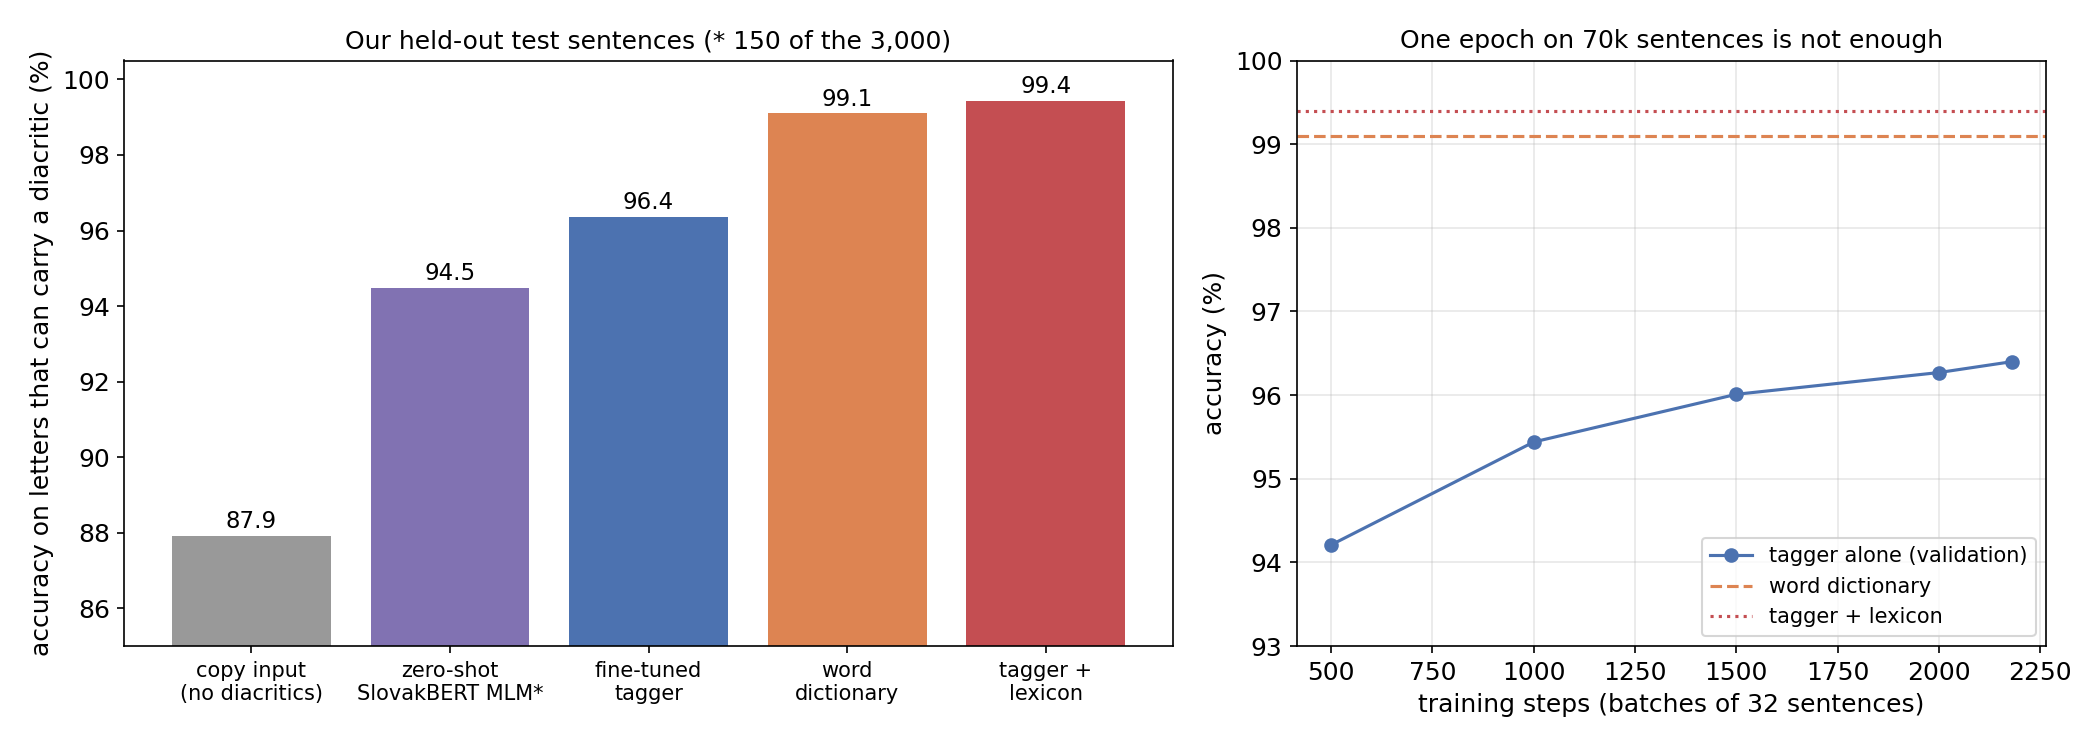
Note how forgiving the metric is: simply copying the input already scores 87.9 % on our test sentences, because most candidate letters carry no diacritic. The interesting range is above 95 %.
Part 1: the data
The pipeline, step by step:
- Stream the compressed dump with
bz2.BZ2Decompressorchunk by chunk; the archive is truncated, so decompression simply stops at the end of the downloaded part. We kept the first 40,194 articles of the main namespace (<ns>0</ns>), skipping redirects. - Remove the wiki markup with
mwparserfromhell: delete top-level templates (infoboxes, citation templates),<ref>,<table>,<math>,<gallery>and<code>tags, thenstrip_code()turns links into their visible text. - Split into sentences at
.,!or?followed by a space and a capital letter (including Á, Č, Š, Ž...), and keep a sentence only if it has 50 to 2,000 characters, at least 60 % letters, ends with sentence punctuation, contains no leftover markup ([ ] { } < > = |), and was not seen before (exact duplicates removed). This drops lists, tables, category lines and formulas. - Build the pairs by applying exactly the statement's map (á to a, ä to a, č to c, and so on, 34 letters) to the original sentence.
- Split by article, not by sentence, with a hash of the article number: 90 % train, 5 % validation, 5 % test. Sentences from the same article share names and topics, so a sentence-level split would leak them.
Statistics (the stats.json of the deliverable): 481,728 sentence pairs (434,066 train, 23,732 validation, 23,930 test), 118.7 characters per sentence on average, 57.2 million characters of which 4.37 million (7.7 %) carry a diacritic, and 461,288 distinct lowercase words. Foreign names and quotations are kept: they are part of real text, and removing diacritics from a word that has none is harmless (the model learns to leave it alone).
Part 2: zero-shot with the masked language model
SlovakBERT was pretrained to fill in masked words of Slovak text, so it "knows" which spelling fits a context. The difficulty is to ask it the right question.
Candidate generation. A word like "pripominaju" has 9 letters that could take a mark, hence thousands of spellings. Our first attempt enumerated all spellings of words with at most 64 of them and skipped the others, which meant leaving every long word untouched: only 89.3 %. The fix uses the model's own tokenizer as a lexicon. SlovakBERT's 50,000 BPE pieces were learned on real Slovak text, so its vocabulary contains pieces like "pripomína" or "jú" but not "pripómina". We index every vocabulary piece by its stripped form and use dynamic programming over the split points of the word to list all spellings that can be written with the fewest pieces (or one more). For "pripominaju" that leaves only 4 candidates (pripomínajú, pripomínaju, pripominaju, pripominajú), and for "polnohospodarstvo" exactly one, "poľnohospodárstvo".
Scoring. For each word, left to right, we replace it by <mask> tokens (one per BPE piece of the candidate), run the model once per distinct , and give each candidate the sum of the log-probabilities of its pieces at the masked positions:
The left context already contains our restored words, so the decision for "ma" (má or ma) can use the restored "mama" before it. The sum naturally penalises spellings that need more, rarer pieces. Result: 94.5 % on 150 test sentences (about 3 s per sentence on the laptop GPU), with no weight touched.
Part 3: fine-tuning
Formulation. Diacritic restoration never changes the length of the text, so it is a classification of each character into 5 classes: no mark, acute (á, é, í, ĺ, ó, ŕ, ú, ý), caron (č, ď, ľ, ň, š, ť, ž), umlaut (ä) or circumflex (ô). SlovakBERT encodes the stripped sentence; for each character we concatenate the hidden state of the BPE token that contains it, an embedding of the character and an embedding of its position inside the token, and a small MLP predicts the class. At decoding, we take the most probable class that is valid for the letter (no circumflex on an "a"). Training: 70,000 sentences, one epoch, batch 32, AdamW at with warm-up and linear decay, about 18 minutes on an Apple laptop GPU (the statement's Colab T4 would allow far more).
The tagger alone reaches 96.4 %, better than zero-shot but disappointing: the learning curve was still rising, and the errors show the model often hesitating about which letter of a token gets the mark ("sprevádzáne" for "sprevádzané", "Slovénská"). A version with a character-level BiGRU on top was slower (0.74 s per step against 0.5) and no better after 500 steps, so we stopped it.
The key idea: combine the network with a lexicon. A simple baseline puts this in perspective: replace every word by its most frequent spelling in the 434,000 training sentences. This "dictionary" reaches 99.1 %: most Slovak words have one correct spelling, and only a minority are truly ambiguous (má or ma, že or ze...). The dictionary is right on frequent words but blind to context; the tagger sees the context but is undertrained. We combine them in a constrained decoder. For each word, the candidates are all spellings observed in the training data plus the tagger's own; the score adds the tagger's log-probabilities of the marks and the log relative frequency of the spelling:
where counts the spelling and all spellings of the stripped word . This is the classic noisy-channel combination of a context model with a prior; is chosen on the validation set (0.5, 1, 2, 4 gave 99.09, 99.31, 99.40, 99.42 %; we keep ). Words never seen in training fall back to the tagger. On the test sentences: 99.44 %, and 73 % of the sentences are fully correct, against 17 % for the tagger alone. The lexicon comes from the part 1 data only, which the rules allow.
Results
All scores are on held-out Wikipedia articles (the official test set is hidden); 3,000 test sentences, 231,156 scored positions, unless stated.
| approach | char accuracy | sentences fully correct |
|---|---|---|
| copy the input (no diacritics) | 87.9 % | |
| zero-shot, enumerate spellings, at most 64 per word | 89.3 % (150 sentences) | |
| zero-shot, BPE-lexicon candidates + masked-LM scores (part 2) | 94.5 % (150 sentences) | |
| fine-tuned tagger alone, 1 epoch on 70k sentences | 96.4 % | 16.6 % |
| most frequent spelling per word (dictionary) | 99.1 % | 63.3 % |
| tagger + lexicon, constrained decoding (part 3) | 99.4 % | 73.4 % |
What to remember
- Turn the task into the right prediction problem. Diacritics keep the text length, so per-character classification over 5 mark types is simpler and more robust than generating text, and an "only valid marks" rule removes impossible outputs.
- A tokenizer is a lexicon. BPE pieces learned on real text tell you which spellings exist; using them to generate candidates is what made the zero-shot masked LM work.
- Always build the simple baseline. A word-frequency dictionary beat our first fine-tuned network by almost 3 points; knowing that changed the plan.
- Combine a context model with a prior. Adding to the network's scores (a noisy-channel decoder) joined the strengths of both and gave the best result.
- Split by document, not by sentence, whenever sentences from one source share vocabulary and names; otherwise the validation score is optimistic.