The problem in brief
You must build a Deep Convolutional GAN that generates MNIST digits, filling three blanks in a notebook: the generator (Q1, 15 points), the discriminator (Q2, 15 points) and the two steps of the adversarial training loop (Q3, 20 points). The architecture must follow the DCGAN guidelines: strided convolutions instead of pooling, BatchNorm, ReLU in the generator with a Tanh output, LeakyReLU in the discriminator. The notebook fixes the rest: latent dimension 100, Adam with learning rate and , batches of 128, 15 epochs.
How you are scored
Coaches grade the code (50 points) and judge the samples by eye; the loss curves must be shown. The objective is the GAN minimax game with binary cross-entropy:
"Looks good" is not a number, so we add an objective check of our own (not part of the official grading). We train a small CNN on real MNIST (98.3 % test accuracy) and use it as a judge: on 10 000 generated digits we measure (i) the share of each predicted class, to detect mode collapse, (ii) the judge's mean confidence and (iii) a Fréchet distance between the judge's features of real test digits and of generated digits, the idea behind FID, computed with an MNIST network instead of Inception:
Two sets of real digits give FD = 2.75, so that is the floor.
First look at the data
The 60 000 MNIST digits are grey images, normalised to so that they live in the same range as a Tanh output. The odd size 28 is the only catch: , so the networks pass through rather than a power of two. Hence the "tricky" block in Q1.
A first baseline
There is no baseline to beat here, but there is a clear failure mode to understand. We removed guideline 2 (no BatchNorm anywhere, everything else unchanged). After 5 epochs, 98 % of the samples are classified as the digit "8", FD is 1 905, and the images are faint grey blobs (right-hand panel below). That is mode collapse: the generator found one output that fools the discriminator and sends every to it. Keep this picture in mind: it shows what the guidelines are for.
The key idea
Q1, the generator: read the size formula. For a transposed convolution, output . With the hinted settings:
| block | layer | size |
|---|---|---|
| 1 | ConvT(100 to 256), | |
| 2 | ConvT(256 to 128), | |
| 3 | ConvT(128 to 64), | |
| 4 | ConvT(64 to 1), , then Tanh |
Blocks 1 to 3 are each ConvTranspose2d, BatchNorm2d, ReLU; the last has no BatchNorm and ends in Tanh. The convolutions use bias=False because the following BatchNorm subtracts the mean anyway.
Q2, the discriminator: the mirror image. For a convolution, output : with , then a convolution with no padding collapses to , one logit. No BatchNorm on the first layer (the DCGAN paper found that normalising the raw images destabilises training), LeakyReLU with slope 0.2 everywhere, no sigmoid at the end, because the loss is BCEWithLogitsLoss, which fuses sigmoid and log for numerical stability.
Q3, the training loop: two subtleties.
# discriminator step: real -> 1, fake -> 0
out_real = D(real_imgs);              loss_real = crit(out_real, ones)
fake = G(torch.randn(bsz, latent_dim, device=dev))
out_fake = D(fake.detach());          loss_fake = crit(out_fake, zeros)   # detach!
d_loss = loss_real + loss_fake;       d_loss.backward(); opt_d.step()
# generator step: make D say "real"
g_loss = crit(D(fake), ones);         g_loss.backward(); opt_g.step()
fake.detach()in the D step cuts the graph: the discriminator update must not push gradients into (otherwise would be trained to help ). In the G step we usefakewithout detach, through the freshly updated .- The generator uses
real_labels: it minimises instead of the minimax term . Both have the same fixed point, but at the start, when easily rejects fakes (), is flat and gives almost no gradient, while is steep exactly there. This is the non-saturating loss from the original GAN paper.
Why BatchNorm saves the day. Normalising each layer's activations over the batch keeps the signal at a sane scale through the 4 layers and couples the samples of a batch, which makes it much harder for to send every to the same image. The DCGAN paper reports exactly the collapse we reproduced without it. We also use the paper's initialisation, weights drawn from .
The full solution
solution.py contains the two networks, the DCGAN initialisation, the training loop exactly as in the notebook (15 epochs, 468 batches each), and the judge. It saves dcgan_generator_weights.pth (the file the submission asks for) and the losses. On an Apple GPU an epoch takes 40 to 90 seconds.
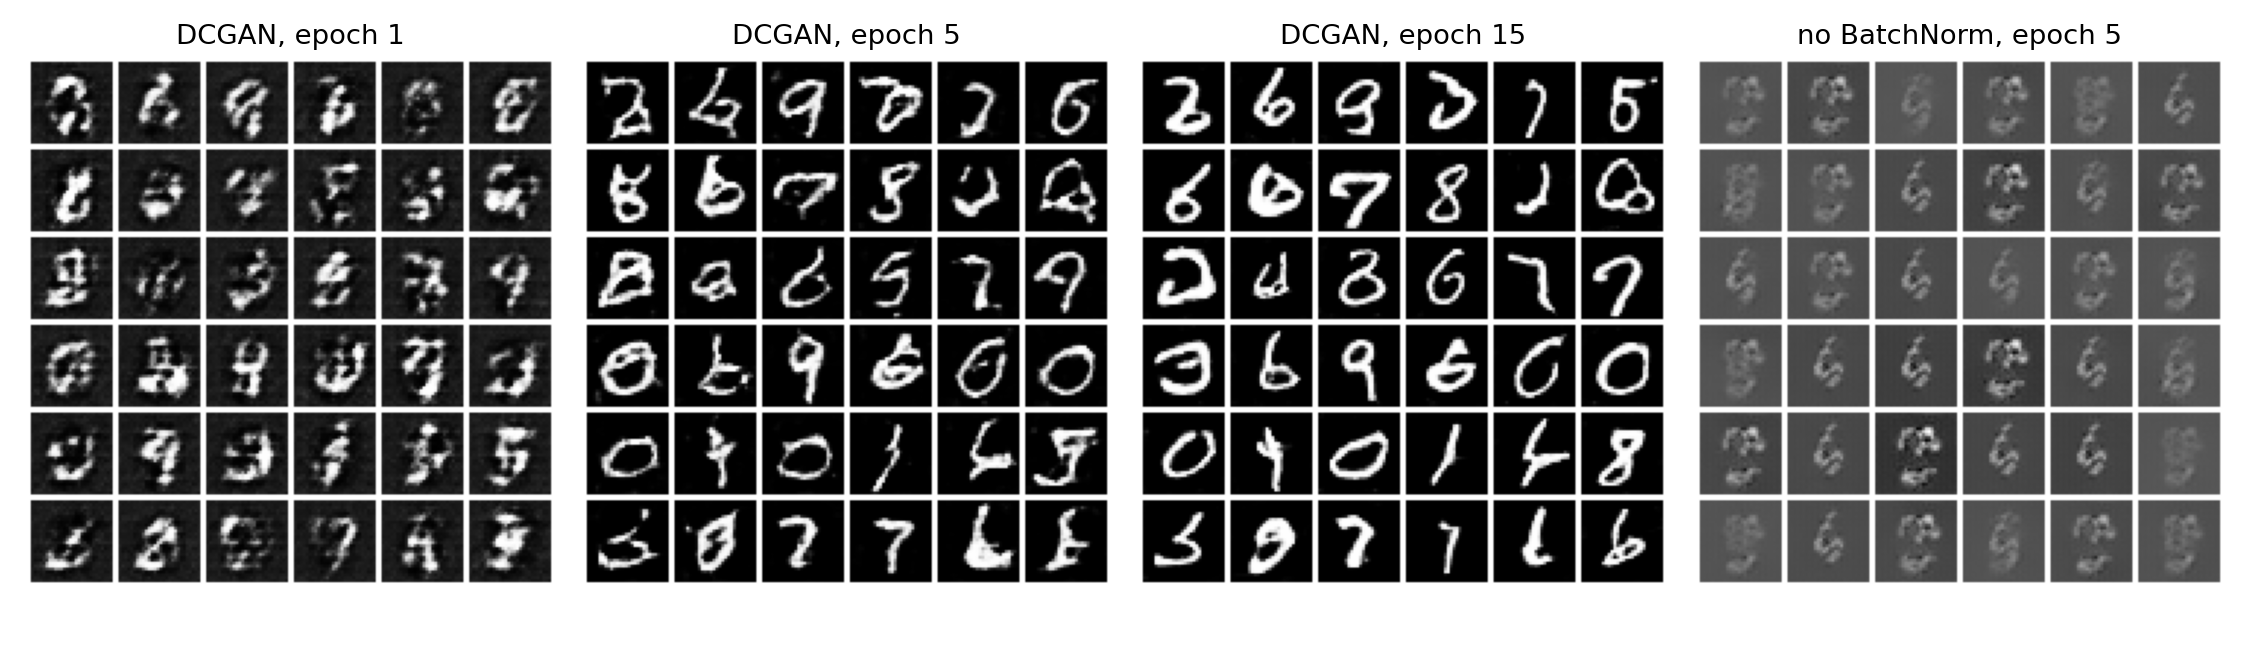
Results
| model | epoch | Fréchet distance (lower is better) | judge confidence | rarest digit share |
|---|---|---|---|---|
| DCGAN | 1 | 494 | 0.65 | 2.7 % |
| DCGAN | 3 | 103 | 0.82 | 5.7 % |
| DCGAN | 5 | 114 | 0.83 | 5.2 % |
| DCGAN | 10 | 48 | 0.87 | 5.5 % |
| DCGAN (final) | 15 | 26.5 | 0.89 | 7.0 % |
| no BatchNorm (failed attempt) | 5 | 1 905 | 0.25 | 0 % (98 % are "8") |
| real vs real (floor) | 2.75 | 0.98 |
With 10 % per digit as perfect coverage, the final generator produces all ten digits with shares between 7 % and 14 %, and its quality keeps improving until the last epoch: more epochs would still help.
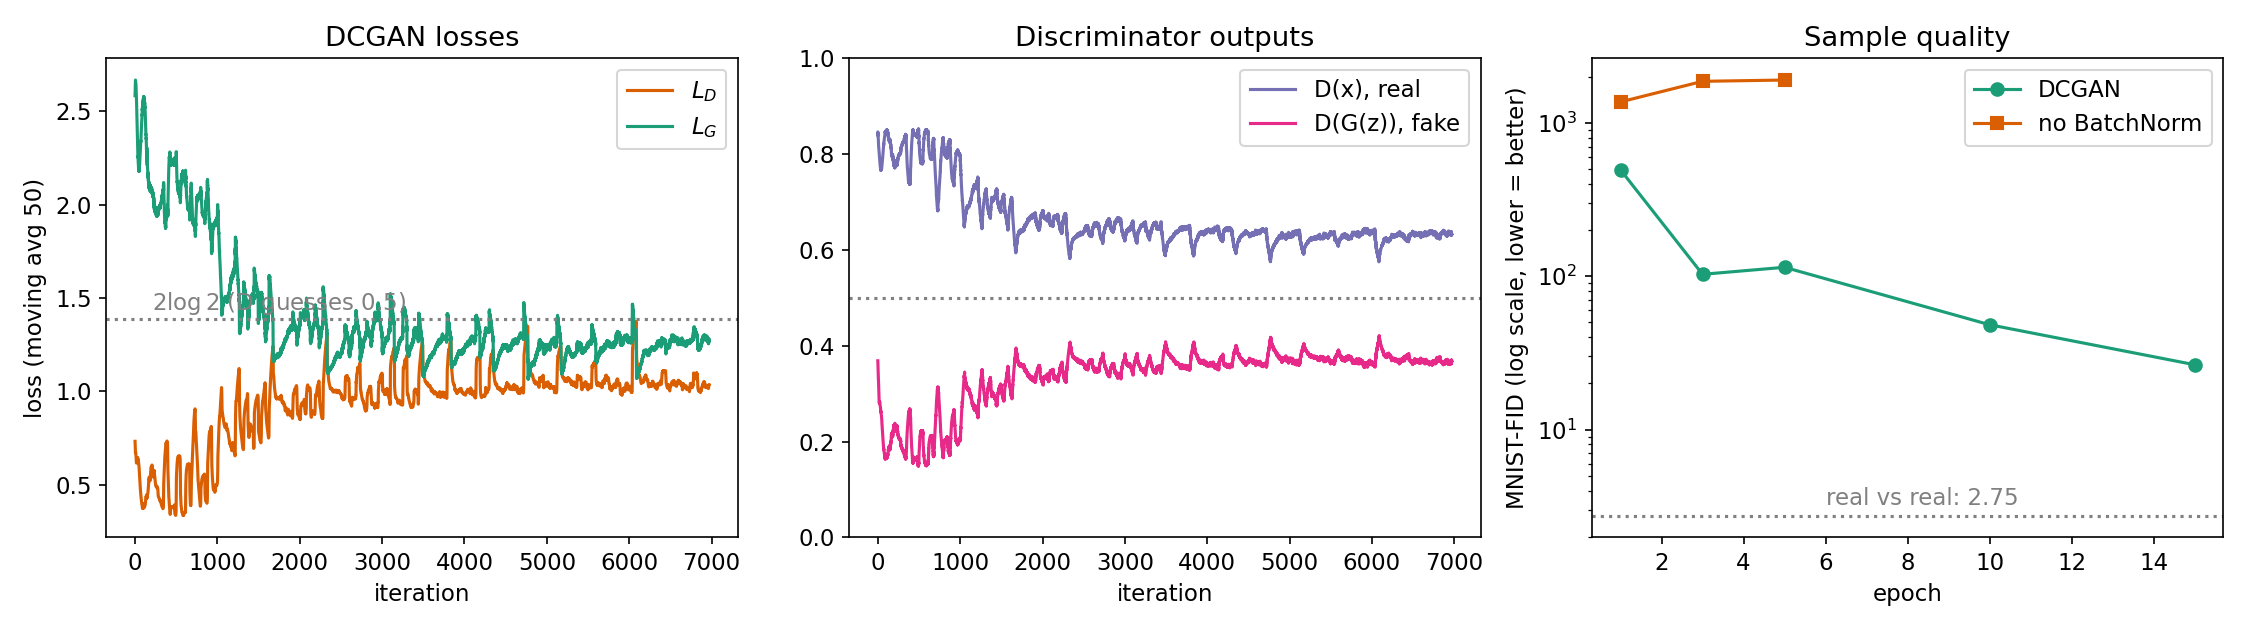
How to read the loss curves, the part students most often get wrong:
- GAN losses do not go to zero, and they should not. They measure a game, not a fit. If were completely fooled ( everywhere), and . Our curves settle near and , with and : a balanced game where keeps a small edge, which is the healthy regime.
- Warning signs would be (the discriminator wins, gets no useful gradient) or falling while the samples all look alike (collapse). The losses barely move between epoch 5 and 15 while the Fréchet distance drops from 114 to 26: losses alone cannot tell you about quality, so always look at samples, and ideally measure them.
What to remember
- Compute every spatial size with the (transposed) convolution formulas before writing the layers; odd sizes like need a non-standard kernel or padding.
detach()the fake batch in the discriminator step, and train the generator with "real" labels (the non-saturating loss) so it gets strong gradients early on.- BatchNorm is not decoration in DCGAN: without it we got mode collapse within five epochs.
- GAN losses describe a balance, not progress. Judge a generator by its samples, and quantify them with a pretrained classifier: class histogram for diversity, a Fréchet distance between feature distributions for realism.