The problem in brief
You receive an English text (letters, digits, a few punctuation marks, spaces and newlines, at most 500 000 characters) in which some characters were replaced by #. Print the text back with every # replaced by the character that was there, with the right case. Anything can be hidden, including spaces and punctuation, but never a newline. There are three test files: in one, at most one letter per word is hidden and spaces and punctuation are never touched; in the others, 10 % and 30 % of all characters are hidden at random. The statement is in Swedish; the sample is the opening of Dickens' A Christmas Carol. There is no training data and the time limit is 1 second.
How you are scored
Each file is worth points. If the file contains hidden characters and you restore of them correctly, you get points, so the total is out of 180. Changing a character that was not a # gives zero for that file, and newlines in your output are ignored. There is no threshold: every restored character counts.
The official test files are hidden, so we built our own: two public-domain novels from Project Gutenberg, A Tale of Two Cities and Pride and Prejudice, cut to 500 000 characters, restricted to the allowed alphabet, and masked in the three ways described above (in the first mode, half of the words get one hidden letter).
First look at the data
The sample shows the three difficulties:
- a hidden letter inside a frequent word (
The#eis There), easy for a human; - a hidden space (
about#that) or punctuation mark (done fo##is done for.): the model must also decide where words end; - runs of several
#(whate##r,Ma##ey), where the candidates multiply.
The most important observation is not in the sample but in the sizes: an input has up to 500 000 characters and only 10 to 30 % are hidden. The input is its own training set. A novel repeats its names (Marley appears unmasked several times), its words and its turns of phrase; learning from the text itself beats any general model of English that would have to fit in the source file.
A first baseline
Replace every # by the most frequent character. In the random modes that is the space, which restores 16 to 17 % of the hidden characters (one character in six is a space); in the one-letter-per-word mode, where spaces are never hidden, the best constant is e, which restores 11.1 %. Any real model has to use the context.
The key idea
Treat the problem as decoding with a language model. A character -gram model gives the probability of a character given the previous ones,
with counts taken from all windows of the input that contain no #. When a long context was never seen, we back off to a shorter one, multiplying by 0.4 for each step ("stupid backoff"); this is crude but fast and works well with this much data.
The essential point is to use both sides of the gap. For a single hidden character at position , the best choice maximises
because every -gram that contains position carries evidence: in S#ORY, a left-only model hesitates between St, Sh and a space, but the following characters ORY settle it. For a run of hidden characters the candidates grow like , so we keep the 8 best partial fillings at each position (beam search), then rescore the finished ones with the right context.
A second, word-level pass fixes what the character model gets wrong inside words. When a token's boundaries are certain (no # just before or after it), its pattern (Gor#on's) is matched against the intact words of the text, and among the matches we pick the one most often seen after the previous word (bigram count, smoothed with the word's own frequency). This brings in long-range knowledge, such as names that appear elsewhere in the book, that a 5-character window cannot see.
The full solution
- Count every -gram of length 1 to 6 that contains no
#(that is, contexts of up to 5 characters). - Scan the text; for each maximal run of
#, run the beam search over the alphabet of characters seen in the text, scoring each filling by the forward model plus the log-probability of the next 5 known characters. - Word pass: tokenise with
[A-Za-z0-9'#]+, and for each token that contained a#with certain boundaries, replace it by the best-matching intact word of the text if one exists. - Print the result; characters that were not
#are never changed, so we can never lose a file by accident.
for sc, f in B:                       # finished candidate fillings of the run
    tot, h = sc, left + f
    for q in range(j, min(n, j + right)):
        if s[q] == '#': break         # stop at the next unknown
        tot += lp(h[-N:], s[q]); h += s[q]
Speed warning. Our Python implementation needs 8 to 50 seconds of CPU on a 500 000-character file (the 30 % file is the slowest: three times more gaps and longer runs). The algorithm is linear in the text length, but the Kattis limit is 1 second, so a real submission must be the same algorithm in C++ (hash maps of -gram counts, a fixed-size beam). The accuracy numbers below are those of the algorithm, not a claim that the Python file passes the time limit.
Results
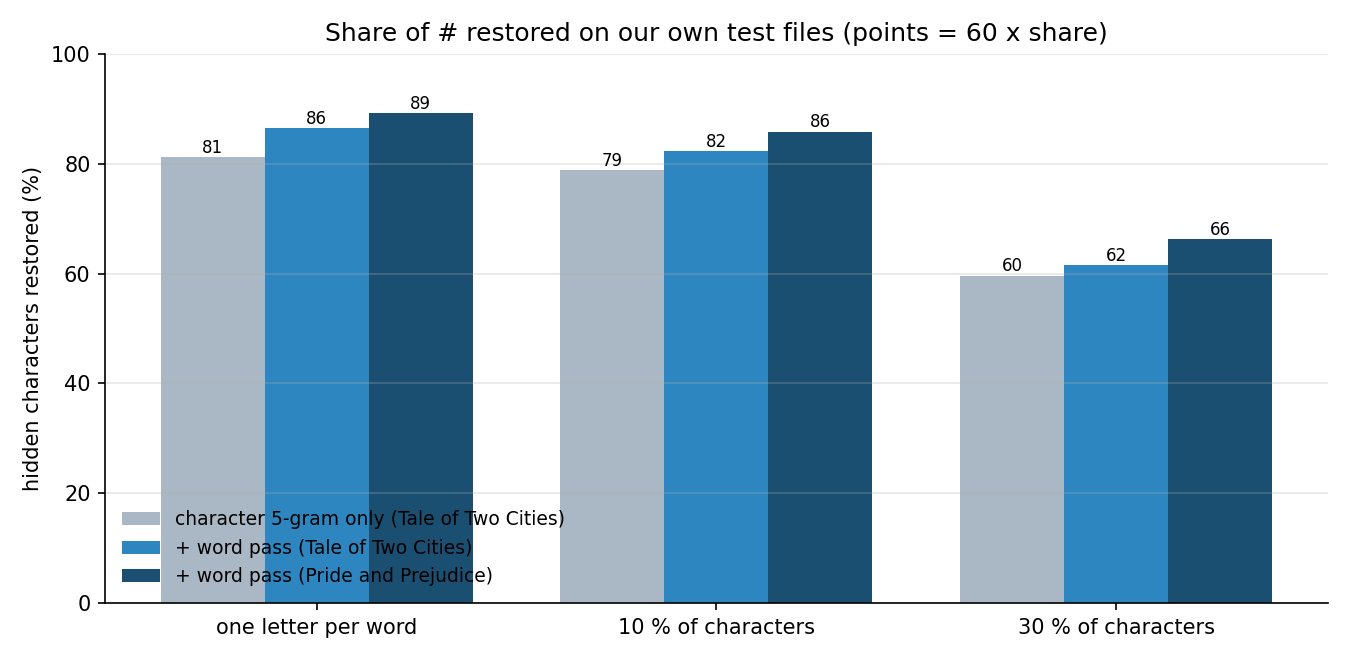
Share of hidden characters restored, and points out of 60 per file, on our self-built tests:
| approach | one letter per word | 10 % hidden | 30 % hidden | total /180 |
|---|---|---|---|---|
| constant character (e, then space) | 11.1 % (6) | 16.5 % (9) | 16.7 % (10) | 25 |
| char 5-gram, left and right context (Two Cities) | 81.2 % (48) | 78.8 % (47) | 59.6 % (35) | 130 |
| + word pass (Two Cities) | 86.5 % (51) | 82.2 % (49) | 61.5 % (36) | 136 |
| + word pass (Pride and Prejudice) | 89.2 % (53) | 85.8 % (51) | 66.3 % (39) | 143 |
| failed idea: also use the bigram with the next word (Two Cities) | 85.2 % (51) | |||
| longer contexts, (char only, Two Cities) | 79.0 % (47) |
Two lessons from the failed rows. Longer contexts are worse: with a fixed amount of text, 8-character contexts are seen too rarely and the crude backoff takes over. And adding the next word to the word pass hurt slightly, because when 30 to 50 % of neighbouring words are themselves damaged the extra evidence is often unreliable and our ad hoc combination over-weights it. The remaining errors are mostly genuinely ambiguous: #he (the or she), #e (he, we, me), capital letters in rare uppercase headings, and long runs at 30 % masking where whole words disappear.
What to remember
- The input can be the training set. When the test document is large and mostly intact, statistics learned from it beat any general model you could fit in the program.
- Use the context on both sides of a gap: every -gram that overlaps the missing character carries evidence, and the right side is as informative as the left.
- Beam search keeps exponential searches affordable: keep a few best partial solutions instead of all fillings.
- Combine levels: a character model handles spaces and punctuation, a word model brings long-range memory (names, rare words).
- Check the time limit early. An algorithm that is right but 20 times too slow in Python needs a compiled implementation, not a cleverer model.