The problem in brief
You are given up to a thousand points in the plane and starting positions for cluster centres (between 2 and 9 of them). The program must run the k-means algorithm from those starting centres and print where the centres end up. The input and output go through standard input and output. The statement fixes the initial centroids precisely so that everybody's algorithm follows the same path.
How you are scored
The output is not compared character by character. The judge measures the quality of your centroids with the k-means objective, the mean squared distance from each point to its nearest centroid:
It compares with the baseline of a single centroid at the mean of all points (the solution):
A test is worth 100 points if your is at least times the reference solution's , and 0 otherwise. Two consequences: the order and the formatting of the centroids do not matter, and a better clustering than the reference is always accepted. The official tests are hidden, so we validate on the sample and on 300 random tests of our own.
The key idea
Lloyd's algorithm alternates two steps, and each one can only lower .
- Assignment. With the centroids fixed, give each point to its nearest centroid. For each point, this picks the smallest of the squared distances, so no other assignment gives a smaller .
- Update. With the clusters fixed, move each centroid to the mean of its points. For a cluster , the function has gradient , which is zero exactly at the mean, . So the mean is the best possible centre for that cluster.
never increases, and there are only finitely many ways to split points into clusters, so the algorithm must stop. We stop as soon as an assignment step changes nothing; then the next update would not move anything either.
What Lloyd's algorithm does not guarantee is the global minimum. Finding the best clustering is NP-hard, and Lloyd only finds a local minimum, which depends on where it starts:
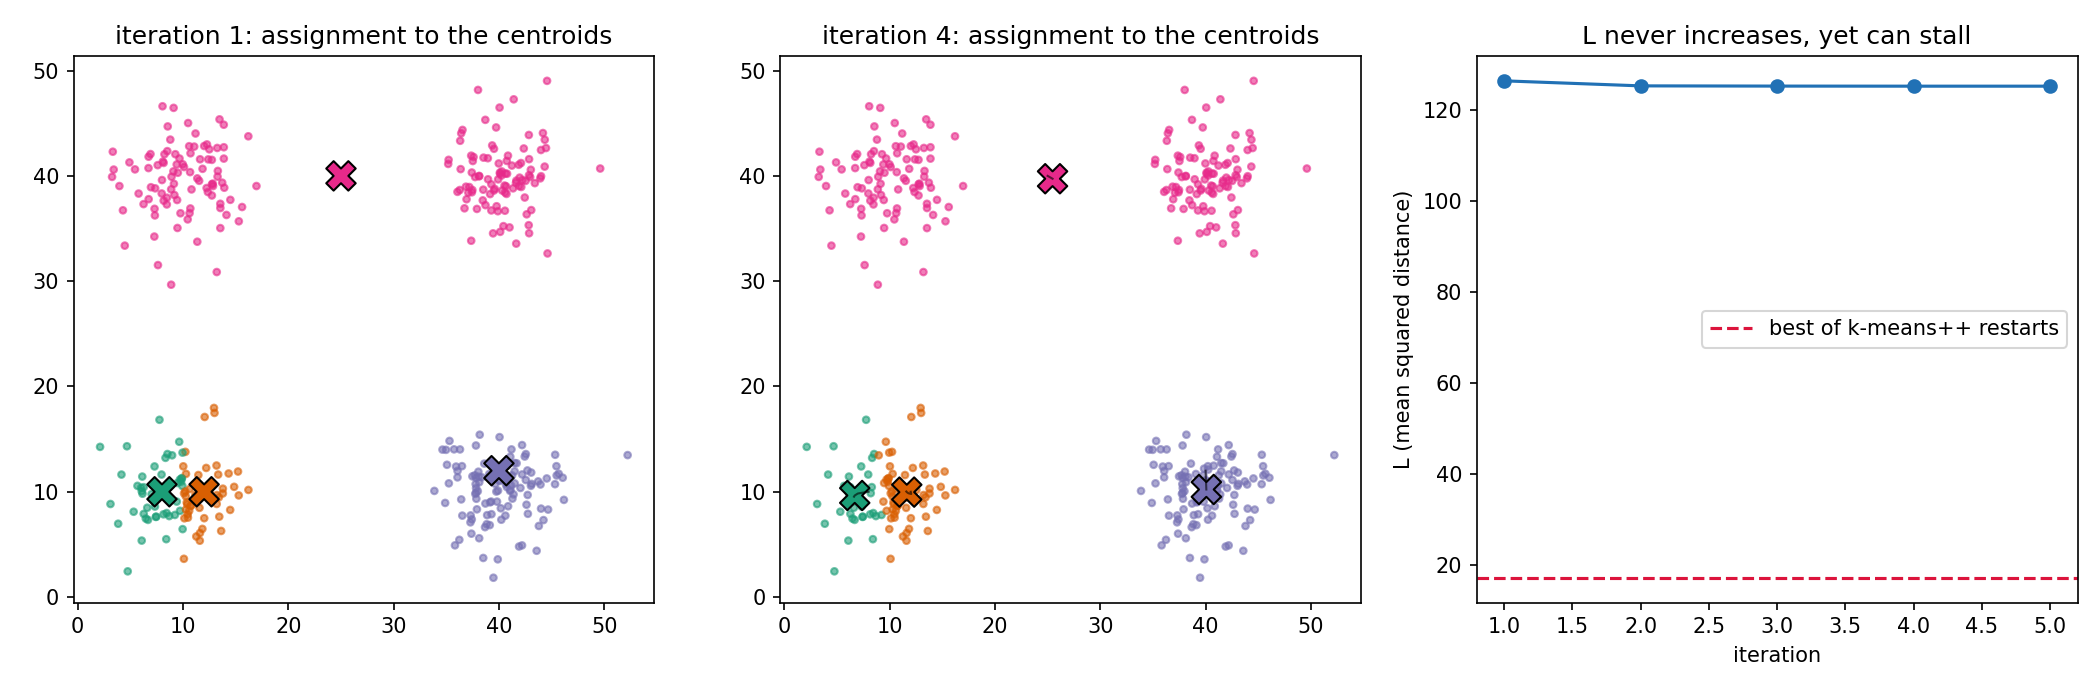
In this example, two centroids start in the same blob and one sits halfway between two blobs. Each step is locally optimal, so nothing ever pulls a centroid across the empty space, and the algorithm stalls at . The good clustering has .
Two details that matter
Empty clusters. The initial centroids are arbitrary points in , so a centroid may get no points at all. Its mean is then undefined. We leave it where it is. Libraries differ here: scikit-learn, for instance, moves an empty centroid to a far-away point. On our 300 random tests, our plain Lloyd matches scikit-learn's Lloyd on all 103 tests with no empty cluster, but on only 6 of the 197 tests where a cluster empties. We cannot know which convention the reference uses.
Insurance, thanks to the metric. Since a lower can only raise , we run Lloyd from the given centroids, which is what the reference does, plus 5 restarts from k-means++ initialisations (each new centre is drawn with probability proportional to its squared distance to the centres already chosen). We print the run with the lowest . Whatever the reference does with empty clusters or ties, our is at most that of the given-start Lloyd, and usually lower.
The full solution
def lloyd(points, cents):
    labels = None
    while True:
        new = [argmin_j(dist2(p, cents[j])) for p in points]   # assignment
        if new == labels:
            return cents                                       # converged
        labels = new
        cents = [mean(points in cluster j) or cents[j] for j]  # update (empty: stay)

best = min([lloyd(pts, init)] + [lloyd(pts, kmeanspp(pts, k)) for _ in range(5)], key=L)
Parsing reads all tokens with split(), so the blank lines of the sample are harmless. Each iteration costs , which is tiny here (, ).
On the sample, the three points on the left go to and the two on the right to , so the centroids become and , and the next assignment changes nothing. The statement's printed answer, "1.5 0" and "-1.5 1.3", is not the mean of any group of the points: it looks like a rounded or mistyped version of . Our centroids give a lower loss ( against ), so they score at least as well under the metric.
Results
| check (300 random tests, up to 999, from 2 to 9) | result |
|---|---|
| sample | , , (statement's printed answer: ) |
| plain Lloyd = scikit-learn Lloyd, no empty cluster | 103 / 103 |
| plain Lloyd = scikit-learn Lloyd, some cluster empties | 6 / 197 (different conventions) |
| with k-means++ restarts, strictly above scikit-learn's | 216 / 300 |
| passes the rule against scikit-learn | 300 / 300 |
What to remember
- Lloyd's algorithm is coordinate descent on : the assignment step is optimal for fixed centres, the mean is optimal for fixed clusters, so decreases until it converges.
- It finds a local minimum only: initialisation matters, which is why practitioners use k-means++ and several restarts (
n_initin scikit-learn). - Decide what happens to empty clusters: it is the classic source of disagreement between implementations.
- Read the scoring rule before coding: here it rewards a lower loss, not an exact match, so restarts are free insurance.