The problem in brief
A delivery robot lives on an map with 8 wall cells and 6 depots. In each episode it must drive to the depot holding a package, pick it up, drive to a second depot and drop it off. Every map is different. You do not write the route planner yourself: you get 400 recorded expert episodes (5 327 observation/action pairs on 100 different maps) and must train a model that imitates them, then lets it drive alone on 200 validation and 1 600 test scenarios on maps it has never seen. Planning or search may not be used to create extra demonstrations, and the final prediction process must be deterministic.
The data is public (the official Drive folder). Because the evaluator only replays your actions in the provided simulator, we can score the official test scenarios exactly by running that simulator ourselves.
How you are scored
The score is the success rate over the test scenarios:
The statement publishes no threshold or reference score for this preparatory task, so there is no official target to compare against. A random policy scores about 0.
First look at the data
Three facts shape everything that follows.
- The expert is a shortest-path planner. Every one of the 400 demonstrations has exactly the length of the BFS shortest route (start to package, package to destination, plus the two pick/drop actions). When several moves are equally short, the expert always prefers the lowest action id (south, then north, then east, then west).
- The maps are new at test time. None of the 1 800 validation and test maps appears among the 100 training maps. The model has to learn how to navigate, not memorise routes.
- The demonstrations only visit "good" states. The expert never makes a mistake, so the data contains no example of how to recover from a bad position. This is the classic weakness of behavioural cloning, and the statement warns about it: one wrong step can lead the robot into a state that the data never covered.
A first baseline
The notebook's baseline flattens the 6 grid planes and the 13-number vector into 397 inputs and trains a 2-layer MLP. It reaches 97 % action accuracy on the training pairs, but only 19.5 % success on validation: the high accuracy is memorisation of 100 maps. Simply masking the invalid actions (moves into walls, pick-up away from the package) during training and inference lifts it to 51 %. Still poor: a flattened grid gives the MLP no notion that cell is next to cell .
The key idea
Navigation is a local rule repeated everywhere on the map, so the model should be one too, and the remaining errors are loops, which the policy itself can break.
1. A convolutional, translation-equivariant policy. Which way to go depends on the walls around you and on where the target is, and this rule is the same in every corner of the map. A convolution applies the same small filter at every cell, so what it learns on one map transfers to every position of every other map. Five convolution layers give each cell a receptive field of , larger than the map: every cell can "see" the whole map. We then read out only the features of the robot's own cell and of its 4 neighbours (in the order south, north, east, west) and map them to the 6 action logits. The network effectively scores "how good is it to step onto this neighbour", which is the shape of the true answer (the neighbour's distance to the target).
We also simplified the input: instead of separate "package" and "destination" planes plus a carrying flag, one plane marks the cell to go to now (the package before pick-up, the destination after). The two halves of an episode become the same problem.
2. The 8 symmetries of the square as free data. Rotating or mirroring a map gives another valid map, and the correct move rotates with it (south becomes east after a quarter turn, and so on). Applying a random symmetry to each mini-batch, and permuting the action labels and the action mask accordingly, multiplies the 100 training maps by 8. Training accuracy drops to about 91 % because the expert's tie-break (prefer south) is not symmetric, but that does not hurt: any tie-breaking among shortest moves is equally good. Validation success goes from 80.5 % to 91 %.
3. Every remaining failure is a loop. We replayed the 18 failed validation episodes: all 18 end with the robot cycling between the same few cells until the 120-step limit, 12 of them before the pick-up and 6 after. The policy is deterministic, so the moment it returns to a state it has already been in, it will repeat the same cycle forever. The figure shows a typical case: the robot steps east into a pocket, decides west is best, then east again.
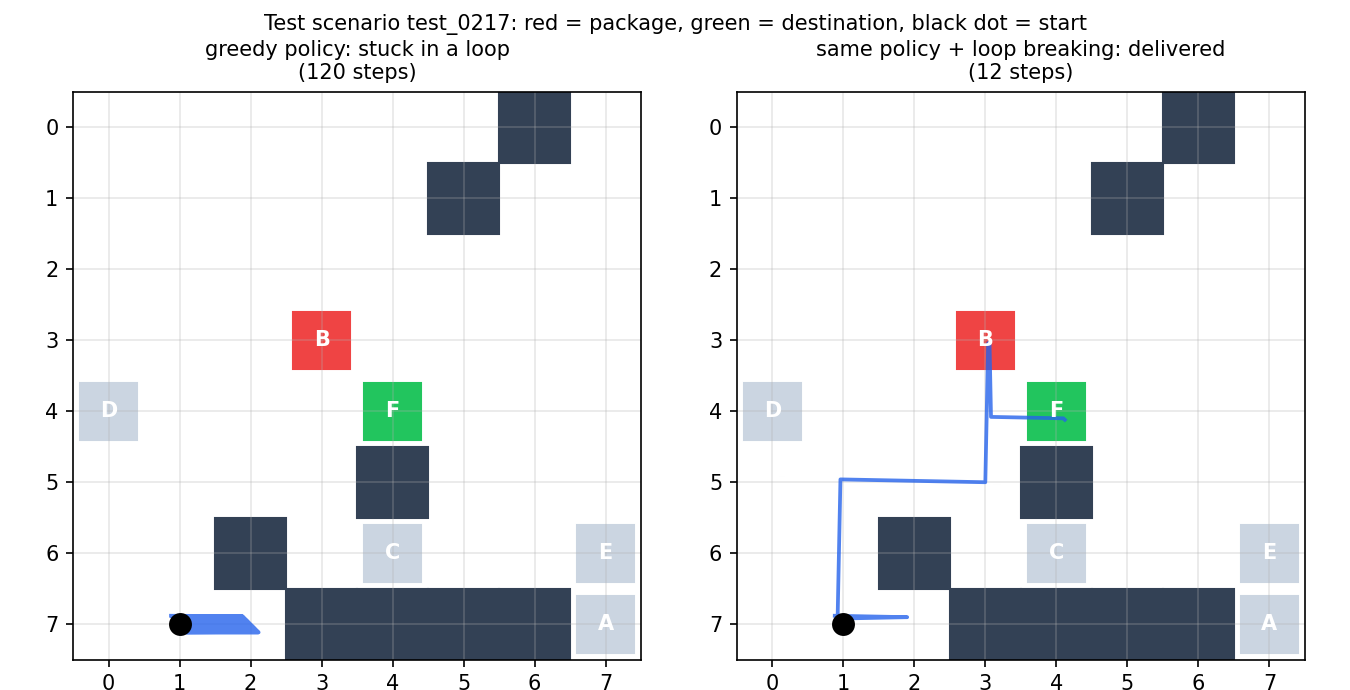
The fix uses only the model's own preferences: never take the same action twice from the same state. If the best action from this state was already tried, it led back here, so it is part of a cycle; take the next-best action instead. Formally, with the set of actions already taken in state ,
This is still deterministic and uses no planner and no knowledge of the map beyond what the model outputs. Each state has at most 4 moves, so the robot cannot cycle forever: it is forced to explore the second choices of the model, which are usually right when the first choice was wrong.
The full solution
- Convert the data safely. The three
.pklfiles come from a third party; we opened them once in a sandbox (no network, restricted writes) and saved scenarios and action lists as JSON. Observations are rebuilt by replaying the actions in a re-implementation of the simulator. - Build the 5 input planes for each of the 5 327 states: wall, free cell, current target, robot, carrying.
- Train the policy (64 channels, 5 conv layers, readout of 5 cells, about 150 k parameters): 40 epochs, Adam with a one-cycle learning rate up to , batch 128, a random dihedral transform per batch, cross-entropy on masked logits. About 2 minutes on 2 CPU threads.
k = rng.integers(8); p = torch.tensor(action_perm(k))   # where each action goes under symmetry k
x, y = dihedral(X[b], k), p[Y[b]]
m = torch.zeros_like(M[b]); m[:, p] = M[b]               # the mask rotates with the actions
loss = F.cross_entropy(model(x).masked_fill(~m, -1e9), y)
- Roll out each test scenario with the masked argmax and loop breaking, and write the action lists to
predictions.jsonlinsidepredictions.zip.
Things that did not help: a value-iteration style network (one convolution applied 20 times with shared weights) fitted the training pairs perfectly (100 % accuracy) but generalised slightly worse (88.5 % without augmentation, 91 % with), and averaging the logits over the 8 symmetries at test time or ensembling two models changed little once loops were handled.
Results
Success rate in the official simulator. Validation = the 200 provided validation scenarios; test = the 1 600 official test scenarios (scored by replaying our actions, exactly like the evaluator).
| approach | valid SR | test SR |
|---|---|---|
| random actions | about 0 | |
| baseline MLP (flattened input) | 0.195 | |
| MLP + action masking | 0.510 | |
| CNN, 5-cell readout, masking | 0.805 | |
| value-iteration style recurrent CNN | 0.885 | |
| recurrent CNN + symmetry augmentation | 0.910 | |
| CNN + symmetry augmentation | 0.915 | 0.942 |
| + test-time averaging over 8 symmetries | 0.915 | |
| CNN + augmentation + loop breaking (final) | 0.990 | 0.992 |
The final model delivers the package in 1 587 of the 1 600 test episodes (99.2 %). Loop breaking alone rescues 80 test episodes. The routes are also efficient: 14.2 steps on average against 13.1 for the shortest possible routes, and 92.5 % of the successful episodes are exactly as short as the expert's. An earlier training run of the same architecture gave 0.995 on validation, so the seed-to-seed variation is about half a point.
What to remember
- Accuracy on demonstrations is not success. 97 % action accuracy gave 19.5 % success. In sequential problems, evaluate the full rollout, and look at how episodes fail.
- Match the architecture to the structure. A grid task with a rule that is the same everywhere calls for convolutions, and a readout at the agent's position turns "classify the whole map" into "score each neighbour".
- Symmetries are free data. Rotations and mirrors of a map are new valid maps, provided you transform the labels (and the masks) consistently.
- A deterministic policy that revisits a state is trapped. Detecting a repeated state and falling back on the model's next-best action is cheap, deterministic, and fixes the covariate-shift failures that behavioural cloning cannot learn to avoid from perfect demonstrations alone.