← Retour à l'épreuve

India INAIO 2026 · Correction IOAI Training

Curve Quest — Solving Polynomial Problems from Graphs

Cette page donne toute la méthode. Lisez-la une fois que vous avez cherché.

Métrique
% correct (tol. 0.05)
Évaluée sur
training set (official test labels are private)
Notre score
80/80 train; test 24/24 checkable agree

Nous avons résolu l'épreuve nous-mêmes : téléchargé les données, mené les expériences et mesuré le score ci-dessous. L'énoncé et les données appartiennent à leurs organisateurs. Cette correction est rédigée en anglais.

The problem in brief

Each problem is a picture of a polynomial drawn on a coordinate grid, with a few marked points such as roots, the yy-intercept or one extra point, plus one sentence of text: "A cubic has zeros at x=−2x=-2, x=−1x=-1 and x=3x=3. The yy-intercept is visible in the graph. Find p(0)p(0)." You must write a local program (no LLM or API calls) that returns the numeric answer. It must also say INCOMPLETE when the picture and the text do not pin the answer down, and CONFLICT when they contradict each other. You get 80 training problems with answers and 50 test problems without. Part Q1 also asks you to sort the problem bank into clusters and to explain how you recognise the two special cases.

The notebook's download server is dead, but the organisers' public Drive folder still holds both CSV files and all 130 images. The test answers are private, so our only exact score is on the 80 training problems. We back it up with an independent consistency check on the test set, described below.

How you are scored

A prediction counts as correct if it is within 0.050.05 of the true number, or if it matches INCOMPLETE / CONFLICT exactly. The score is the percentage of correct test problems:

score=100N∑i=1N1[a^i=ai].\text{score} = \frac{100}{N}\sum_{i=1}^{N} \mathbf{1}\big[\hat a_i = a_i\big].

Performance is worth 6 of the 30 points. The rest goes to the write-up (clusters, special cases, approach) and to the code. The organisers publish no accuracy threshold.

First look at the data

Reading the 80 questions, they fall into a handful of templates. Parsing the text puts each problem in one cluster, and the counts are:

clusterexampletrain count
roots in the text, scale in the picture, find a value or a coefficient"zeros at 1 and 3, use the yy-intercept, evaluate p(−1)p(-1)"41 (3 of them INCOMPLETE)
leading coefficient in the text, zeros only on the picture, find p(0)p(0)"leading coefficient −2-2, its zeros are labelled"7 (all CONFLICT)
parabola meets a line, find the other crossing"ff has leading coefficient −2-2, yy-intercept (0,−15)(0,-15), g(x)=2x−3g(x)=2x-3"10
one root hidden as '?'"leading coefficient 2, zeros at −2-2 and 44, third zero marked '?'"8
roots aa and 2a2a"p(x)=2(x−a)(x−2a)p(x)=2(x-a)(x-2a), find the positive aa"8
roots in arithmetic progression"roots aa, a+2a+2, a+4a+4, find aa"6

Every case reduces to the same object: p(x)=c∏i(x−ri)p(x) = c\prod_i (x-r_i), where some of cc, the rir_i, aa or the '?' root are unknown. The marked points, and the curve itself, add equations.

The pictures come in two plotting styles. Most use mathtext labels such as (0, −3)(0,\,-3), axes through the origin and labelled yy ticks. A second style, slightly squarer (about 700 by 697 pixels), has plain labels such as (0,-14). Here is a striking leak: all 10 INCOMPLETE/CONFLICT training problems, and only those, use the second style. A "lazy" classifier on image size would get the special cases right for free. We do not use this, because it explains nothing and would collapse on any new generator. It is still worth noting in Q1, since it tells you the organisers built the special cases with a separate script.

What makes a problem INCOMPLETE? The unknown that the question asks about is not fixed by anything. In the three training cases, the question asks for the leading coefficient of a curve whose only labelled points are its roots, and the picture has no yy tick labels (see train_078). Every multiple c q(x)c\,q(x) goes through the same roots, so cc can be anything.

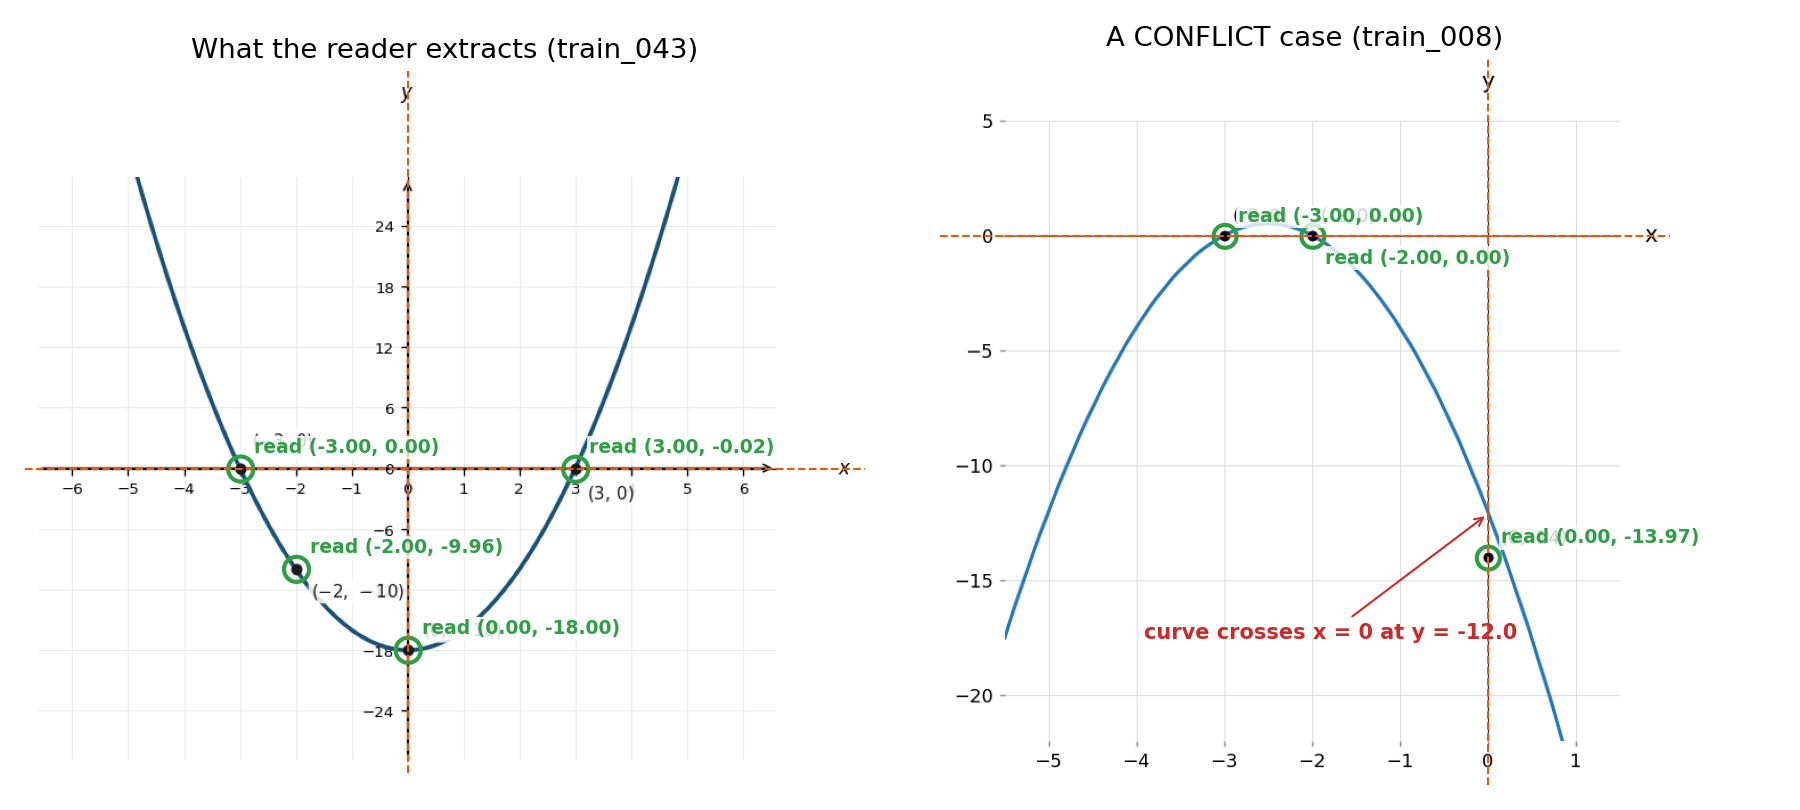
What makes a problem a CONFLICT? There are more equations than unknowns, and they disagree. In train_008, the text says leading coefficient −2-2 and the picture shows roots −3-3 and −2-2, so p(0)=−2⋅3⋅2=−12p(0) = -2\cdot 3\cdot 2 = -12. The picture, however, labels the yy-intercept as (0,−14)(0,-14), and that dot is visibly off the drawn curve, which does pass through −12-12.

What the image reader extracts, and a CONFLICT case

A first baseline

Text only. If we solve from the sentence alone, ignoring the picture, we only get the problems that need no scale: the three INCOMPLETE ones, plus the symmetric-roots case of train_007. There, the coefficient of x3x^3 for roots ±2,±4\pm2, \pm4 is −c∑ri=0-c\sum r_i = 0, whatever cc is. That gives 4 / 80 (5 %). The picture carries almost all of the information.

OCR of the labels. The obvious next step is to OCR every "(x, y)" label with a small local OCR model (RapidOCR, an ONNX model installed with pip) and plug the numbers into the algebra. That gives 60 / 80 (75 %). The failures teach something. The OCR drops minus signs (it reads (−1,−8)(-1,-8) as "(-1,2 8)" and −12-12 as "12"), it merges labels that the curve crosses, and some problems have no scale label at all.

The key idea

Do not read the numbers; measure the picture. A plot is a linear map between pixels and data:

x=αx u+βx,y=αy v+βy,x = \alpha_x\,u + \beta_x, \qquad y = \alpha_y\,v + \beta_y ,

where (u,v)(u,v) are pixel coordinates. If we recover this map, every marked dot gives its coordinates by pure geometry, and labels become a mere cross-check. The map is fixed by structure that is far more reliable than OCR:

  • the axis lines are the longest dark rows and columns, which gives y=0y=0 and x=0x=0 to the pixel;
  • the light grid lines give the pixel length of one tick step. We choose the unit (0.5, 1 or 2) that makes the root dots agree with the roots quoted in the text;
  • for the yy scale we use the tick labels, but only their magnitudes ∣vtick∣/∣ rowtick−rowy=0∣|v_{\text{tick}}| / |\,\text{row}_{\text{tick}} - \text{row}_{y=0}|, combined by a median. The OCR loses signs and sometimes reads "9-" for −9-9, and the median of magnitudes is immune to both.

Dots are found by morphological opening with a 7-pixel disk on the dark (or red) pixels. Text strokes and axis lines are 1 to 2 pixels thick and disappear, while the filled markers survive. Black dots are known points. Red dots are the unknowns (the '?' root, "(a,0)(a,0)", the other crossing). With this reader, the dot coordinates agree with the readable labels 205 times out of 212, and the 7 disagreements are all OCR mistakes, not geometry mistakes.

Then solve exactly, and let the solver decide INCOMPLETE and CONFLICT. Each black dot (xk,yk)(x_k,y_k) off the axis adds an equation p(xk)=ykp(x_k)=y_k. Sympy solves the system with rational arithmetic, which turns the two special labels into mathematical facts:

  • no solution means CONFLICT: an overdetermined system that disagrees;
  • a target that still contains a free symbol means it is undetermined.

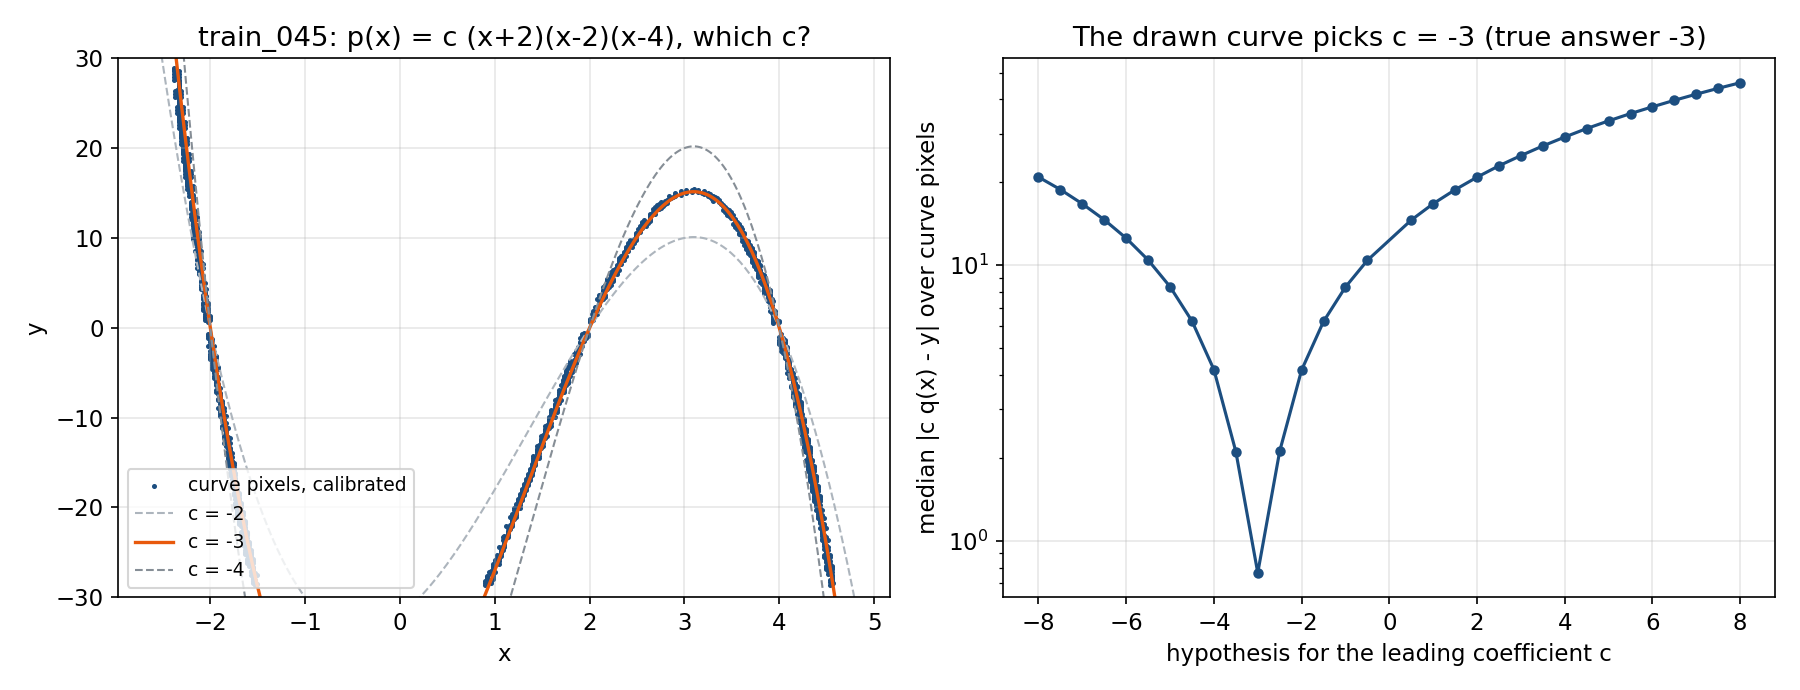
And the drawn curve is data too. In train_045, nothing gives the scale except the curve itself: the yy-intercept, p(0)=48cp(0) = 48c, is off the plot. Once the axes are calibrated, every blue pixel is a noisy sample (xj,yj)(x_j, y_j) of pp. For the few unknowns left, we enumerate small integer or half-integer hypotheses that satisfy all labelled equations, and keep the one with the smallest robust residual:

θ^=arg⁡min⁡θ median⁡j ∣ pθ(xj)−yj ∣.\hat\theta = \arg\min_{\theta}\ \operatorname{median}_j \,\big|\,p_\theta(x_j) - y_j\,\big| .

We use the median rather than least squares because steep parts of the curve and the legend give large, meaningless errors. A problem is declared INCOMPLETE only when no calibrated yy axis exists, which is exactly the situation in the three training cases. The same curve also gives a second CONFLICT test: a labelled dot more than 8 pixels from the nearest curve pixel cannot be a point of pp.

The curve alone determines the leading coefficient

The full solution

  1. OCR once per image (RapidOCR, local ONNX model, about 0.3 s per image on 2 CPU threads). Only numeric tokens (ticks) and parenthesised tokens (labels) are kept.
  2. Calibrate: axis lines, grid spacing, yy scale from tick magnitudes. Fallbacks: bottom-row xx ticks when the yy-axis is off-screen; the dots' own labels when no yy tick is readable.
  3. Detect dots (opening + connected components), convert them to data coordinates, round to integers (all labels are integers), and measure each dot's distance to the curve.
  4. Parse the question with about 20 regular expressions: degree (parabola/quadratic, cubic, quartic, or the number of roots), leading coefficient ("unit", "monic", "2(x−a)(x−2a)2(x-a)(x-2a)"), numeric roots (including p(−2)=p(2)=p(4)=0p(-2)=p(2)=p(4)=0), symbolic roots a+ka+k or 2a2a, a '?' root, line data for intersections, and the target, read from the last sentence (a value p(k)p(k), the coefficient of xjx^j, the leading coefficient, the yy-intercept, a root, aa, or the other crossing).
  5. Intersections use Vieta instead of solving for ff. With f(x)=Ax2+Bx+Cf(x)=Ax^2+Bx+C and g(x)=mx+kg(x)=mx+k, the crossings are the roots of Ax2+(B−m)x+(C−k)Ax^2+(B-m)x+(C-k), so their product is (C−k)/A(C-k)/A and the other crossing is x2=(C−k)/(Ax1)x_2 = (C-k)/(A x_1). You do not even need BB. The one exception is when the labelled crossing is the yy-intercept (C=kC=k): then x1=0x_1=0 and the product says nothing, so BB is read from the curve (train_015).
  6. Solve as described above. Admissibility filters keep the "positive value of aa" and a '?' root distinct from the known ones.
sols = sp.solve(eqs, unknowns, dict=True) if eqs else [{}]
if eqs and not sols: return 'CONFLICT'                  # overdetermined and inconsistent
vals = [float(T.subs(s)) for s in sols if admissible(sp.simplify(T.subs(s)), s)]
if vals: return fmt(vals[0])                            # determined by the labels
if R.get('curve') is None: return 'INCOMPLETE'          # nothing else carries a scale
# otherwise: integer hypotheses that satisfy every label, ranked by the median residual on the curve

learn_model only builds the OCR engine. Nothing is fitted: the handful of thresholds (7-pixel opening, 8-pixel curve distance, 4 % tick agreement) were set by looking at the training images. The training score is therefore an optimistic estimate, and the honest question is how well it transfers.

Checking the test predictions without labels. The pictures contain their own answer key for many problems, in the form of the red markers: the '?' root sits at the true root, the "(?, ?)" crossing at the true crossing, the "(0, ?)" dot at the true yy-intercept, and the "(a,0)(a,0)" dot at aa. Our solver never uses these red positions (it treats them as unknowns), so they make an independent check. On the test set, 24 of 24 such predictions match the red markers exactly. Of the remaining 26, 6 are special cases (3 INCOMPLETE pictures with no yy ticks, 3 CONFLICT cases where for instance 1⋅(0+2)(0−2)=−41\cdot(0+2)(0-2)=-4 but the label says −1-1), and the numeric ones follow from labelled points by the same algebra that scores 100 % on train.

Results

approachtrain (80, labels public)
text only, ignore the picture4 / 80 (5 %)
OCR the "(x, y)" labels, then solve60 / 80 (75 %)
geometric reading of the dots (calibrated axes), no curve67 / 80 (84 %)
first full version (curve used only for cc)73 / 80 (91 %)
+ curve fit for every remaining unknown, Vieta exception at x1=0x_1=0, degree from the root count80 / 80 (100 %)

Test set: 50 predictions written (10 INCOMPLETE/CONFLICT, 40 numbers). The official labels are private. 24 of the 24 predictions that can be checked against the picture's own red markers agree.

The jump from 84 % to 100 % came from three fixes, each found by reading a failure. When the picture has a '?' root but no labelled yy-intercept, the curve must supply the scale. "p(x)=2(x−a)(x−2a)p(x)=2(x-a)(x-2a)" without the word "parabola" was being parsed as a quartic. And the parabola-line problem whose labelled crossing is the yy-intercept makes the Vieta formula useless.

What to remember

  • Turn a picture into numbers through its structure, not its text. Axis lines, grid spacing and marker shapes are drawn exactly; OCR is the noisy part. Use OCR only for what geometry cannot give (the scale), and combine it robustly (a median of magnitudes).
  • Write one general model, and let the solver classify the special cases. "Undetermined" and "inconsistent" are exactly what a symbolic solver reports for under- and overdetermined systems. You do not need a separate classifier for INCOMPLETE and CONFLICT.
  • Every pixel of a curve is a measurement. When labels are missing, a robust fit over a small, discrete hypothesis space (c∈{±12,±1,… }c\in\{\pm\tfrac12,\pm1,\dots\}) is exact and cheap.
  • Use Vieta's formulas when they apply. The product of the roots gives the other intersection without knowing the middle coefficient, and it tells you exactly when that shortcut breaks (x1=0x_1=0).
  • Look for leaks, then refuse to depend on them. Image size alone predicts every special case here, a fact worth reporting in Q1. A solver that relies on it learns nothing about the problems and would collapse on a new generator.
Code complet (solution.py)
"""CurveQuest (INAIO 2026 stage 2): answer polynomial-graph questions from a picture + a sentence.

Pipeline:  OCR (RapidOCR, local ONNX model)  ->  read the picture geometrically
           (axis lines, grid spacing, tick labels -> pixel/data calibration; marked dots; curve pixels)
        ->  parse the question with regular expressions into unknowns + target
        ->  solve the constraints exactly with sympy:  no solution = CONFLICT,
            target still free = INCOMPLETE, otherwise fall back on the drawn curve.
Run:  python solution.py  (expects curvequest_train.csv, curvequest_test.csv, images/ in work/)
"""
import re, sys, itertools
import numpy as np, cv2, sympy as sp
import pandas as pd
from PIL import Image
from typing import Any

# ---------------------------------------------------------------- 1. reading the picture
def load(path):
    return np.array(Image.open(path).convert('RGB')).astype(int)
def find_dots(a):
    r,g,b = a[...,0],a[...,1],a[...,2]
    mx, mn = a.max(-1), a.min(-1)
    dark = (mx < 90) & (mx - mn < 30)
    red = (r > 110) & (r - g > 60) & (r - b > 60)
    out=[]
    for kind,m in (('black',dark),('red',red)):
        m = m.astype(np.uint8)
        m = cv2.morphologyEx(m, cv2.MORPH_OPEN, cv2.getStructuringElement(cv2.MORPH_ELLIPSE,(7,7)))
        n,lab,st,cen = cv2.connectedComponentsWithStats(m)
        for i in range(1,n):
            x,y,w,h,area = st[i]
            if 20 <= area <= 400 and 0.6 < w/h < 1.6:
                out.append(dict(kind=kind, px=float(cen[i][0]), py=float(cen[i][1]), area=int(area)))
    return out
INT = re.compile(r'^-?\d+$')
def clean(t):   # OCR'd tick text -> integer string (tick marks are often read as a trailing '-')
    t = t.replace('−','-').replace('–','-').replace('—','-').replace(' ','')
    return t.strip('-') if not t.startswith('-') else '-' + t[1:].strip('-')
def ticks(ocr):
    xs=[]
    for text,box,conf in ocr:
        t = clean(text)
        if INT.match(t):
            b=np.array(box); xs.append((float(t), b[:,0].mean(), b[:,1].mean(), b[:,0].max()))
    return xs
def lines(a):
    """row of the x-axis, column of the y-axis (long dark lines), columns/rows of the light grid"""
    sat = a.max(-1)-a.min(-1); H, W = sat.shape
    dark = (a.max(-1) < 110) & (sat < 30)
    lg = (sat == 0) & (a[...,0] >= 200) & (a[...,0] <= 240)
    rows, cols = dark.sum(1), dark.sum(0)
    ry = int(rows.argmax()) if rows.max() > 0.5*W else None
    cx = int(cols.argmax()) if cols.max() > 0.5*H else None
    if ry is not None and rows[ry+1] > 0.5*W: ry += 0.5   # 2-px thick line
    if cx is not None and cols[cx+1] > 0.5*H: cx += 0.5
    vg = np.where(lg.sum(0) > 0.4*H)[0]; hg = np.where(lg.sum(1) > 0.4*W)[0]
    return ry, cx, vg, hg
def spacing(pos):
    pos = np.array(sorted(pos), float)
    if len(pos) < 3: return None
    d = np.diff(pos); d = d[d > 5]
    return float(np.median(d)) if len(d) else None
def calibrate(a, ocr):
    ry, cx, vg, hg = lines(a)
    tk = ticks(ocr)
    # ---- x: zero at the y-axis line, one unit = vertical grid spacing (x ticks are integers)
    xs = spacing(vg)
    xcal = None
    if cx is not None and xs: xcal = (1/xs, -cx/xs)
    else:   # fall back to the x tick labels on the bottom row (RANSAC-free: median of pairwise slopes)
        bot = [t for t in tk if t[2] > 0.9*a.shape[0]]
        if len(bot) >= 2:
            P = np.array([t[1] for t in bot]); V = np.array([t[0] for t in bot])
            sl = np.median([(V[j]-V[i])/(P[j]-P[i]) for i in range(len(P)) for j in range(i+1,len(P)) if abs(P[j]-P[i])>10])
            b = np.median(V - sl*P); xcal = (sl, b)
    # ---- y: zero at the x-axis line, scale from y tick labels (median of value / pixel offset)
    ycal = None
    if ry is not None:
        cand = [t for t in tk if t[0] != 0 and abs(ry - t[2]) > 10 and t[2] < 0.93*a.shape[0]]
        groups = {}
        for t in cand: groups.setdefault(round(t[3]/12), []).append(t)
        best = None
        for g in groups.values():
            s = np.array([abs(t[0])/abs(ry - t[2]) for t in g])   # OCR often drops minus signs: use magnitudes
            m = np.median(s); ok = np.abs(s - m) < 0.04*abs(m)
            if ok.sum() >= 2 and (best is None or ok.sum() > best[1]): best = (float(np.median(s[ok])), int(ok.sum()))
        if best: ycal = (-best[0], best[0]*ry)
    return xcal, ycal, (ry, cx)
LAB = re.compile(r'\(\s*([^,]+?)\s*[,.]\s*([^)]+?)\s*\)')
def parse_label(t):
    t = t.replace('−','-').replace(' ','')
    m = LAB.search(t)
    if not m: return None
    def num(s):
        try: return float(s)
        except: return s
    return num(m.group(1)), num(m.group(2))
def read_image(path, ocr, text_roots=()):
    a = load(path)
    xcal, ycal, (ry, cx) = calibrate(a, ocr)
    dots = find_dots(a)
    labs = []
    for text, box, conf in ocr:
        p = parse_label(text)
        if p: b = np.array(box); labs.append((p, b[:,0].min(), b[:,1].mean()))
    # the vertical grid may be drawn every 0.5, 1 or 2 units: pick the unit that makes
    # the dots agree with their own labels and with the roots quoted in the question
    if xcal:
        def score(k):
            s = 0
            for d in dots:
                x = k*(xcal[0]*d['px']+xcal[1])
                best = min(labs, key=lambda l: np.hypot(l[1]-d['px'], l[2]-d['py']), default=None)
                if best and isinstance(best[0][0], float) and abs(best[0][0]-x) < 0.15: s += 1
                if ry is not None and abs(d['py']-ry) < 4 and any(abs(r-x) < 0.15 for r in text_roots): s += 1
            return s
        k = max([1, 0.5, 2, 0.25, 4], key=score)
        xcal = (k*xcal[0], k*xcal[1])
    if ycal is None and ry is not None:   # no readable y ticks: use the dots' own labels (y = 0 at the x-axis line)
        s = []
        for d in dots:
            best = min(labs, key=lambda l: np.hypot(l[1]-d['px'], l[2]-d['py']), default=None)
            if best and np.hypot(best[1]-d['px'], best[2]-d['py']) < 60 and isinstance(best[0][1], float) and best[0][1] != 0 and abs(ry-d['py']) > 10:
                s.append(best[0][1]/(ry - d['py']))
        if s: m = float(np.median(s)); ycal = (-m, m*ry)
    for d in dots:
        d['x'] = xcal[0]*d['px']+xcal[1] if xcal else None
        if ycal: d['y'] = ycal[0]*d['py']+ycal[1]
        elif ry is not None and abs(d['py']-ry) < 4: d['y'] = 0.0
        else: d['y'] = None
        # nearest parsed label (labels sit up-right or down-right of their dot)
        best = min(labs, key=lambda l: np.hypot(l[1]-d['px'], l[2]-d['py']), default=None)
        d['label'] = best[0] if best and np.hypot(best[1]-d['px'], best[2]-d['py']) < 60 else None
    # curve pixels (the blue polynomial), in data coordinates when both axes are calibrated
    blue = (a[...,2] - a[...,0] > 50) & (a[...,2] > 100)
    py_, px_ = np.nonzero(blue)
    curve = None
    if xcal and ycal:
        curve = np.c_[xcal[0]*px_+xcal[1], ycal[0]*py_+ycal[1]]
    for d in dots:   # distance (pixels) from the dot centre to the nearest curve pixel
        d['dcurve'] = float(np.min(np.hypot(px_-d['px'], py_-d['py']))) if len(px_) else None
    return dict(dots=dots, xcal=xcal, ycal=ycal, axis=(ry, cx), curve=curve)

# ---------------------------------------------------------------- 2. reading the question and solving
X = sp.Symbol('x')
NUM = r'(-?\d+(?:\.\d+)?)'
def norm(q):
    q = q.replace('$', '').replace('\\,', '').replace('−', '-').replace('{', '').replace('}', '')
    return re.sub(r'\s+', ' ', q)
def parse(question):
    q = norm(question)
    P = {}
    P['deg'] = 2 if re.search(r'parabola|quadratic', q) else 3 if re.search(r'cubic|degree-3', q) else 4 if re.search(r'quartic|degree-4', q) else None
    P['inter'] = bool(re.search(r'intersect|crossing|meeting|meets|reference line|crosses? the line', q)) and 'f(x)' in q
    # leading coefficient
    m = re.search(r'leading coefficient ' + NUM, q)
    lc = float(m.group(1)) if m else None
    if re.search(r'unit leading coefficient|monic', q): lc = 1.0
    m = re.search(r'p\(x\) = (-?\d*)\s*\(x - a\)', q)
    if m: lc = float(m.group(1)) if m.group(1) not in ('', '-') else (1.0 if m.group(1) == '' else -1.0)
    P['lc'] = lc
    # symbolic roots: a, a + k, 2a
    sym = []
    if re.search(r'\ba\b', q) and re.search(r'roots?|sequence|progression|form', q):
        if re.search(r'\b2a\b', q): sym = [(1, 0), (2, 0)]
        else:
            offs = sorted({0} | {int(k) for k in re.findall(r'a ?\+ ?\(?(\d+)', q)})
            sym = [(1, k) for k in offs]
        if len(sym) < 2: sym = []
        if 'consecutive' in q and not sym: sym = [(1, 0), (1, 1), (1, 2)]
    if re.search(r'consecutive integer roots|three consecutive', q) and not sym: sym = [(1, 0), (1, 1), (1, 2)]
    P['sym'] = sym
    P['qroot'] = "'?'" in q
    # numeric roots quoted in the text
    roots = []
    if not P['inter']:
        roots = [float(r) for r in re.findall(r'x = ' + NUM, q.split('Evaluate')[0])]
        m = re.findall(r'p\(' + NUM + r'\) =(?= p| 0)', q)
        if m: roots = [float(r) for r in m]
        # drop "at x = k" belonging to the question (What does the polynomial equal at x = 0)
        tail = re.search(r'equal at x = ' + NUM, q)
        if tail: roots = roots[:-1]
    P['roots'] = roots
    # intersection data: f(x) = A x^2 + B x + C with A, C given ; g(x) = m x + k
    if P['inter']:
        m = re.search(r'y-intercept \(0,\s*' + NUM + r'\)', q)
        P['C'] = float(m.group(1)) if m else None
        if 'x-axis' in q and 'g(x)' not in q: P['g'] = (0.0, 0.0)
        else:
            m = re.search(r'g\(x\) = ([^.]*?)(?:\.|,| is| also| plotted| at| together)', q)
            e = sp.sympify(m.group(1).replace(' ', '').replace('x', '*x').lstrip('*').replace('-*x', '-x').replace('+*x', '+x'), locals={'x': X})
            pe = sp.Poly(e, X)
            P['g'] = (float(pe.coeff_monomial(X)), float(pe.coeff_monomial(1)))
    # target: read the last request in the question
    t = re.sub(r'\([^()]*y-intercept[^()]*\)', '', q).strip()
    sent = [s for s in re.split(r'(?<=[.?])\s', t) if s][-1]
    m = re.search(r'coefficient of x\^?(\d)?', sent)
    if m and 'leading' not in sent[max(0, m.start()-8):m.start()]: P['target'] = ('coef', int(m.group(1) or 1))
    elif 'leading coefficient' in sent: P['target'] = ('coef', P['deg'])
    elif re.search(r'p\(' + NUM + r'\)', sent): P['target'] = ('val', float(re.search(r'p\(' + NUM + r'\)', sent).group(1)))
    elif re.search(r'equal at x = ' + NUM, sent): P['target'] = ('val', float(re.search(r'equal at x = ' + NUM, sent).group(1)))
    elif re.search(r'y-intercept|vertical intercept', sent) and not re.search(r'\ba\b', sent): P['target'] = ('val', 0.0)
    elif P['inter'] or 'x-coordinate' in sent: P['target'] = ('other',)
    elif re.search(r'root|zero', sent) and P['qroot']: P['target'] = ('qroot',)
    else: P['target'] = ('a',)
    return P
def solve(P, R):
    """P: parsed question, R: what the image reader saw. Returns a string answer."""
    dots = R['dots']
    def snap(v): return float(round(v)) if v is not None else None
    black = [d for d in dots if d['kind'] == 'black' and d['x'] is not None]
    on_axis = [d for d in black if d['y'] is not None and abs(d['y']) < 0.3]
    off_axis = [d for d in black if d['y'] is not None and abs(d['y']) >= 0.3]
    if P['inter']:
        A, C = P['lc'], P['C']; mm, kk = P['g']
        if A is None or C is None: return 'INCOMPLETE'
        cand = [d for d in black if not (abs(d['x']) < 0.3 and abs(d['y'] - C) < 0.5)]
        if not cand:
            if abs(C - kk) > 0.5 or R.get('curve') is None: return 'INCOMPLETE'
            # the y-intercept is itself a crossing: f - g = A x^2 + (B - m) x, fit B on the curve
            xs, ys = R['curve'][:, 0], R['curve'][:, 1]
            B = min([b/2 for b in range(-24, 25)], key=lambda b: np.median(np.abs(A*xs**2 + b*xs + C - ys)))
            return fmt(-(B - mm) / A)
        x1, y1 = snap(cand[0]['x']), snap(cand[0]['y'])
        if abs(mm*x1 + kk - y1) > 0.5: return 'CONFLICT'       # labelled crossing is not on the line
        # product of the roots of f - g = 0 is (C - k)/A
        return fmt((C - kk) / (A * x1)) if x1 != 0 else 'INCOMPLETE'
    # polynomial p(x) = c * prod(x - r)
    c = sp.Rational(P['lc']).limit_denominator(100) if P['lc'] is not None else sp.Symbol('c')
    unknowns = [c] if P['lc'] is None else []
    roots = [sp.Rational(r).limit_denominator(100) for r in P['roots']]
    if not roots and not P['sym']:
        roots = [sp.Integer(int(snap(d['x']))) for d in sorted(on_axis, key=lambda d: d['x'])]
    a, q = sp.Symbol('a'), sp.Symbol('q')
    if P['sym']: roots += [k*a + o for k, o in P['sym']]; unknowns.append(a)
    if P['deg'] is None: P['deg'] = len(roots)
    if P['qroot'] or len(roots) < P['deg']: roots.append(q); unknowns.append(q)
    p = c * sp.prod([X - r for r in roots])
    eqs = [sp.Eq(p.subs(X, snap(d['x'])), snap(d['y'])) for d in off_axis]
    # a labelled point that is not on the drawn curve contradicts the figure
    for d in off_axis:
        if d.get('dcurve') is not None and d['dcurve'] > 8: return 'CONFLICT'
    t = P['target']
    if t[0] == 'coef': T = sp.Poly(sp.expand(p), X).coeff_monomial(X**t[1]) if t[1] else sp.expand(p).subs(X, 0)
    elif t[0] == 'val': T = p.subs(X, t[1])
    else: T = q if t[0] == 'qroot' else a
    def admissible(v, sol):
        if v.free_symbols or not v.is_real: return False
        if 'a' in [str(u) for u in unknowns] and a in sol and P['sym'] and P['sym'][-1][0] == 2 and sol[a] <= 0: return False
        if q in sol and any(sp.simplify(sol[q] - r) == 0 for r in roots if r != q): return False
        return True
    sols = sp.solve(eqs, unknowns, dict=True) if eqs else [{}]
    if eqs and not sols: return 'CONFLICT'
    vals = [float(T.subs(s)) for s in sols if admissible(sp.simplify(T.subs(s)), s)]
    if vals: return fmt(vals[0])
    # still undetermined: enumerate small integer hypotheses that satisfy every label,
    # and keep the one whose graph best matches the drawn curve
    if R.get('curve') is None: return 'INCOMPLETE'
    free = list(unknowns)
    grid = {u: ([k/2 for k in range(-8, 9) if k] if u == c else list(range(-8, 9))) for u in free}
    xs, ys = R['curve'][:, 0], R['curve'][:, 1]
    span, best = np.ptp(ys) + 1e-9, None
    for combo in itertools.product(*[grid[u] for u in free]):
        sub = dict(zip(free, [sp.Rational(v).limit_denominator(4) for v in combo]))
        if any(sp.simplify(e.lhs.subs(sub) - e.rhs) != 0 for e in eqs): continue
        if not admissible(sp.simplify(T.subs(sub)), sub): continue
        f = sp.lambdify(X, p.subs(sub))
        err = float(np.median(np.abs(f(xs) - ys))) / span
        if best is None or err < best[0]: best = (err, float(T.subs(sub)))
    return fmt(best[1]) if best else 'CONFLICT'
def fmt(v):
    return str(int(round(v))) if abs(v - round(v)) < 1e-6 else f'{v:.4g}'

# ---------------------------------------------------------------- 3. notebook interface
def learn_model(train_path: str) -> Any:
    """Nothing to fit: the 'model' is the OCR engine plus the hand-built reader/solver,
    whose few thresholds were chosen by looking at the 80 training problems."""
    from rapidocr_onnxruntime import RapidOCR
    return {'ocr': RapidOCR(intra_op_num_threads=2)}
def predict(model: Any, image_path: str, question: str) -> str:
    res, _ = model['ocr'](image_path)
    ocr = [[t, [[float(a) for a in p] for p in box], float(c)] for box, t, c in (res or [])]
    P = parse(question)
    try: return solve(P, read_image(image_path, ocr, P['roots']))
    except Exception: return 'INCOMPLETE'
def _is_correct(pred, true):
    pred, true = str(pred).strip(), str(true).strip()
    if true.upper() in ('INCOMPLETE', 'CONFLICT'): return pred.upper() == true.upper()
    try: return abs(float(pred) - float(true)) < 0.05
    except ValueError: return False
if __name__ == '__main__':
    root = sys.argv[1] if len(sys.argv) > 1 else 'work'
    model = learn_model(f'{root}/curvequest_train.csv')
    for name in ('train', 'test'):
        df = pd.read_csv(f'{root}/curvequest_{name}.csv')
        preds = [predict(model, f"{root}/{r.image_path}", r.question) for r in df.itertuples()]
        if 'answer' in df: print(f'{name}: {np.mean([_is_correct(p, t) for p, t in zip(preds, df.answer)]):.1%} correct')
        else:
            pd.DataFrame({'problem_id': df.problem_id, 'predicted_answer': preds}).to_csv('curvequest_submission.csv', index=False)
            print(f'{name}: {len(preds)} predictions written')