The problem in brief
This is the online selection round of the 2025 exhibition AI event attached to the Indonesian national science olympiad (OSN), set on the TLX TOKI platform in Indonesian. It contains 40 answer boxes in seven themed blocks worth 1000 points in total: problem solving (a game and a path-counting puzzle), statistics, conditional probability, a least-squares line, word vectors (including decoding an alien vocabulary), output sizes of convolution layers, and a toy "language model" that recognises species from DNA strings. Most answers are a number, a short string or one option.
Every answer below was checked by computation (exhaustive search, dynamic programming, exact fractions or least squares): see the solution code.
How you are scored
Each box has the points printed in the statement, from 10 to 80 (for example 40 for the game, 80 for the path count, 13 for each word or DNA item), with no penalty for wrong answers. Short answers must match a fixed format (A x B, X.Y; A.B, lower-case words...), so the format is part of the answer. The platform does not show the answer key, so there is no official target score beyond getting each item exactly right.
Answers at a glance
| items | answers |
|---|---|
| 1 (game) | b: Nesy always wins |
| 2 (IOAI paths) | 174 |
| 3 (variance of duplicated sample) | c: |
| 4 | 2N |
| 5, 6, 7 (cinema) | 48, 28, 21 |
| 8, 9 (linear model) | 1192.7; 112.4; 7.4 |
| 10, 11 (vectors) | 25; 18 18 |
| 12 to 21 (alien words) | Gohok wanita, Subi kalah, Matot ayah, Befar ibu, Dursit ratu, Gien menang, Ibakuz senang, Gelon raja, Wazuke pria, Nusgen sedih |
| 22 to 25 (conv sizes) | 32 x 32, 14 x 14, 16 x 16, 15 x 7 |
| 26 to 40 (DNA) | Ikan, Kucing, Kucing, Bebek, Bebek, Ikan, Ikan, Bebek, Kucing, Bebek, Ikan, Kucing, Ikan, Kucing, Bebek |
Problem solving (items 1 and 2)
Item 1: the number-line game. Nesy always wins. This is a symmetry strategy. Nesy first plays the centre (a rational number). After that, whenever Nyoo plays , Nesy answers with its mirror image . Why is the mirror move always legal?
- Before Nyoo's move, the set of chosen numbers is symmetric around . Nyoo's is more than 1 away from every chosen number, so by symmetry is more than 1 away from every chosen number too.
- must also be far from itself: , because had to be more than 1 away from the centre .
So Nesy can always reply and is never the one stuck; the game is finite because the chosen points are more than 1 apart. A random-play simulation of this strategy (for to 9) never fails.
Item 2: counting IOAI on the board. 174. A path is a sequence of 4 cells, each one a king's move (8 directions) from the previous one, and revisiting a cell is allowed. Count with dynamic programming: for each cell, keep the number of ways to arrive there having spelled the prefix so far.
- Start: every
Icell has 1 way. - For
O,A,Iin turn: the count of a cell holding the next letter is the sum of the counts of its 8 neighbours. - The answer is the sum of the final counts.
This makes operations instead of listing every path. Revisits come for free: a path may step back onto a cell it has already used, and the counts handle this automatically.
Statistics (items 3 and 4)
Item 3: c, . Doubling the sample (every value appears twice) leaves the mean and the sum of squared deviations doubles: . With the sample variance, which divides by ,
Duplicating data makes the sample look larger than it is, and the correction shrinks. (With the population formula, dividing by , the two would be equal. Since the statement says "variansi sampel", the convention applies.)
Item 4: 2N. Let be the mean of the first people. The combined mean is
Probability (items 5 to 7)
Each probability is a sum over the three film types, weighted by (law of total probability).
- Item 5: 48. , counting "popcorn only" and "both".
- Item 6: 28. .
- Item 7: 21. By Bayes, with "only a soft drink":
(Reading the condition as "bought a soft drink, possibly with popcorn" would give 23.7 %, so 23. The text says "only a soft drink", hence 21.)
Linear model (items 8 and 9)
Item 8: 1192.7. With , the predictions are 797, 743, 635. The residuals are , so .
Item 9: 112.4; 7.4. Setting the two partial derivatives of to zero gives the usual least-squares line:
The statement rightly insists on rounding after optimising, and the minimal loss is .
Word vectors (items 10 to 21)
Item 10: 25. , and , a 3-4-5 triangle.
Item 11: 18 18. . That is almost exactly sedih : "happy + lose - win sad", the same analogy trick as "king + woman - man queen".
Items 12 to 21: decoding the alien words. "The structure between the words is the same" means the relations (difference vectors) are preserved. Look for one transformation that maps the 10 Indonesian points onto the 10 alien points.
- A quick human approach: compare difference vectors. , and among the alien words exactly. Likewise, the extreme points correspond: the highest Indonesian word
rajamaps to the highest alien wordGelon, the lowestmenangtoGien, and so on. - A systematic check: we tried every affine map fixed by three anchor pairs, refined it by optimal assignment (Hungarian algorithm) plus least squares, and kept the best one. It is essentially a translation by about (the linear part is close to the identity) with small noise, and its residual is less than a third of that of the next candidate. No exact isometry or affine map exists, so the "same structure" is only approximate, as with real embeddings.
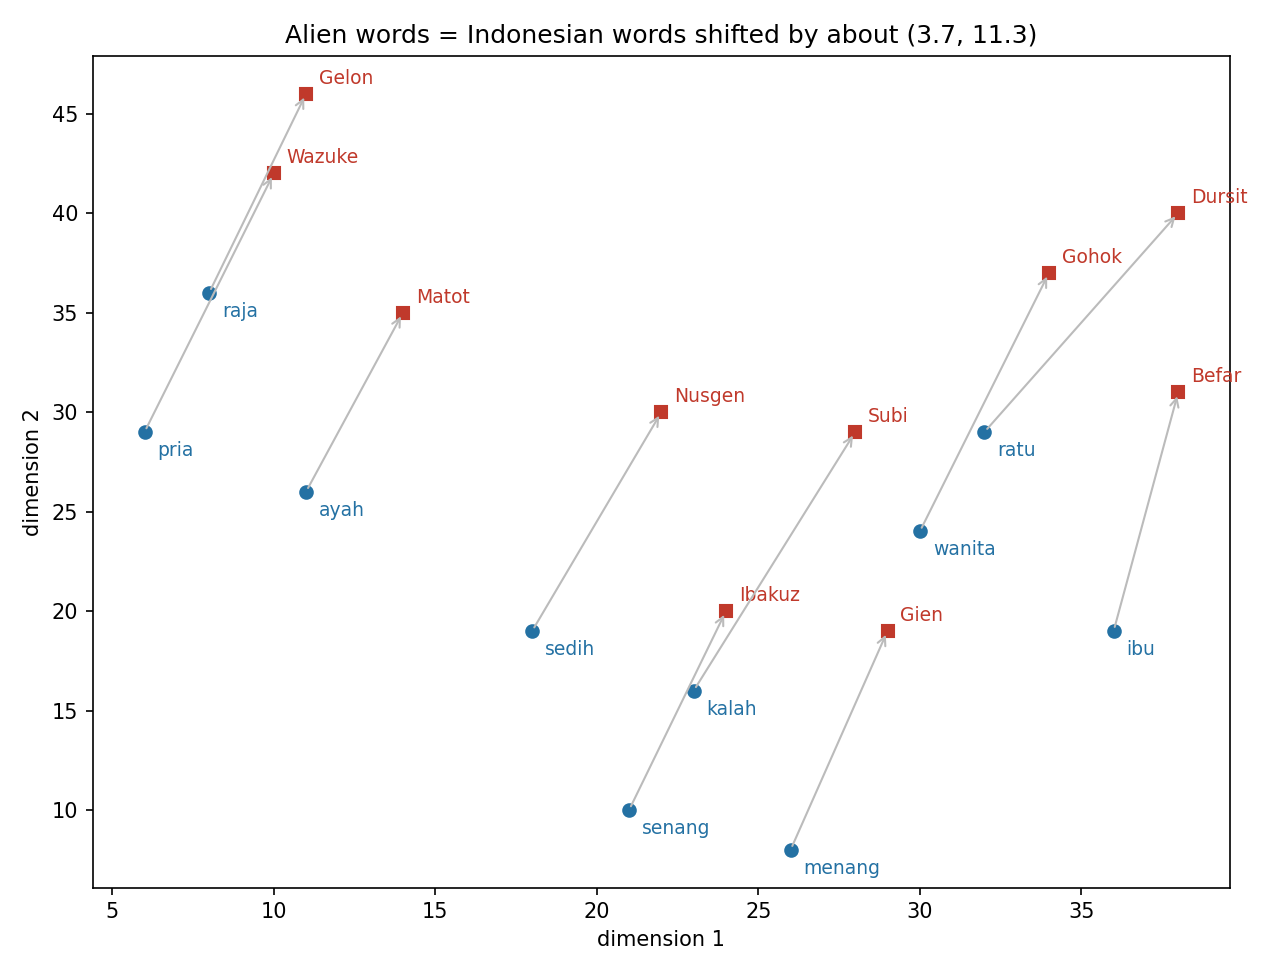
| alien | Gohok | Subi | Matot | Befar | Dursit | Gien | Ibakuz | Gelon | Wazuke | Nusgen |
|---|---|---|---|---|---|---|---|---|---|---|
| Indonesian | wanita | kalah | ayah | ibu | ratu | menang | senang | raja | pria | sedih |
Convolution output sizes (items 22 to 25)
For each axis, , with input size , kernel size , padding on each side and stride . "Same" padding means . Height and width are computed separately.
- Item 22:
32 x 32, since "same" with stride 1 keeps the size. - Item 23:
14 x 14: . - Item 24:
16 x 16: , then "same" () with stride 2 gives , then the convolution keeps 16. - Item 25:
15 x 7, tracking (height, width): . Layer 4's kernel with stride halves only the width; the last layer gives and .
DNA "language model" (items 26 to 40)
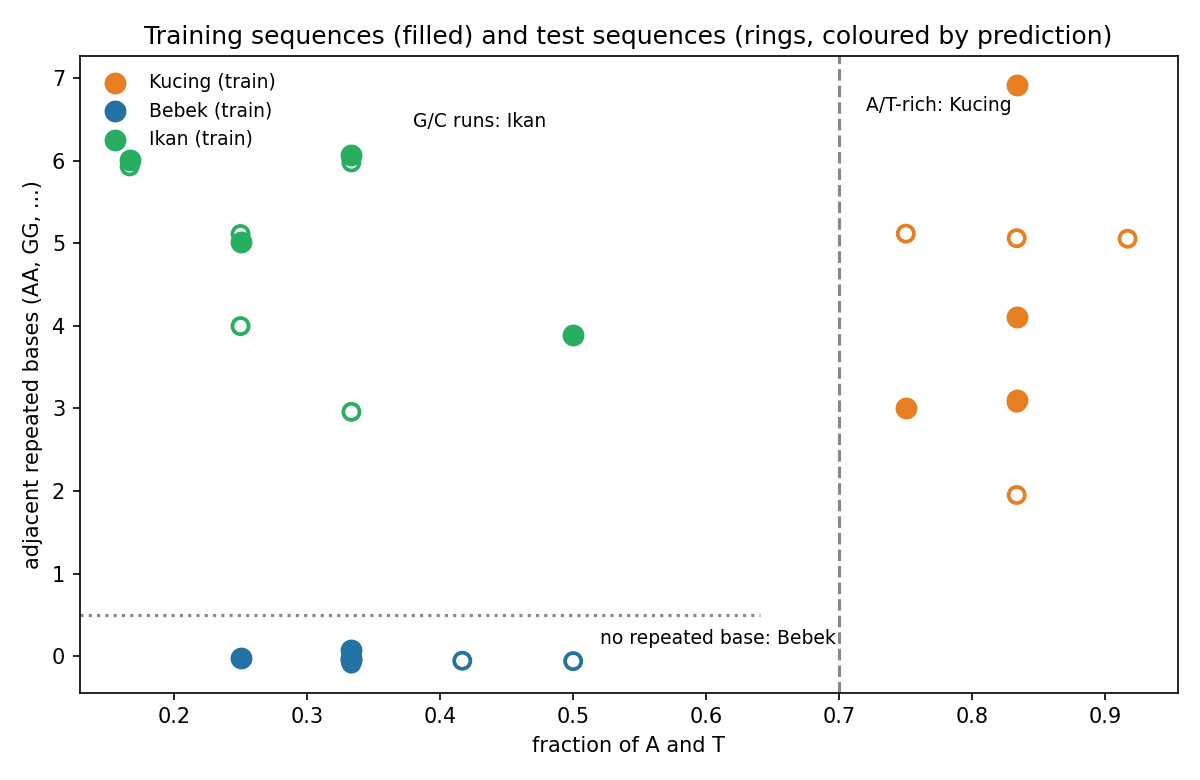
Look at the 12 training sequences before reaching for a model. Two numbers separate the species perfectly:
- Kucing (cat) sequences are A/T-rich: 75 to 83 % of their bases are A or T, against at most 50 % for the others.
- Bebek (duck) sequences never repeat a base twice in a row: they alternate, like
CGCGAGAGAGCG. - Ikan (fish) sequences are G/C-rich with runs such as
GGGGandCCCC(4 to 6 adjacent repeats).
The rule "A/T fraction at least 0.7: Kucing; otherwise no adjacent repeat: Bebek; otherwise Ikan" fits all 12 training sequences. A character bigram language model per species gives the same answers on all 15 test sequences: it learns with add-one smoothing and picks the species whose model gives the sequence the highest likelihood. The bigram model is the natural tool here, because "repeats" and "alternation" are exactly properties of consecutive pairs, which a single-base (unigram) model cannot see: a unigram model confuses Bebek and Ikan, which share the same G/C content.
What to remember
- Symmetry strategies solve many two-player games: take the centre, then mirror. Always check that the mirrored move is legal.
- Count paths with dynamic programming over (cell, prefix), not by listing them; revisits are then free.
- Duplicating data does not add information: it shrinks the correction and makes the sample look larger than it is.
- Word-vector analogies are vector arithmetic: compare difference vectors, or fit one transformation plus an assignment, to align two embedding spaces.
- Convolution sizes: , axis by axis, layer by layer.
- Look at the data before modelling: two hand-made features, or a bigram model that captures pairs of neighbours, beat any heavy machinery on 12 examples.